Encore

Every great performance earns an encore.

Seven apps of practice taught the platform to measure, receipt and ship. This is the proof — one elite-grade web experience, built end-to-end by the agent, every number sourced to a committed receipt.

See the loopRead the receipts
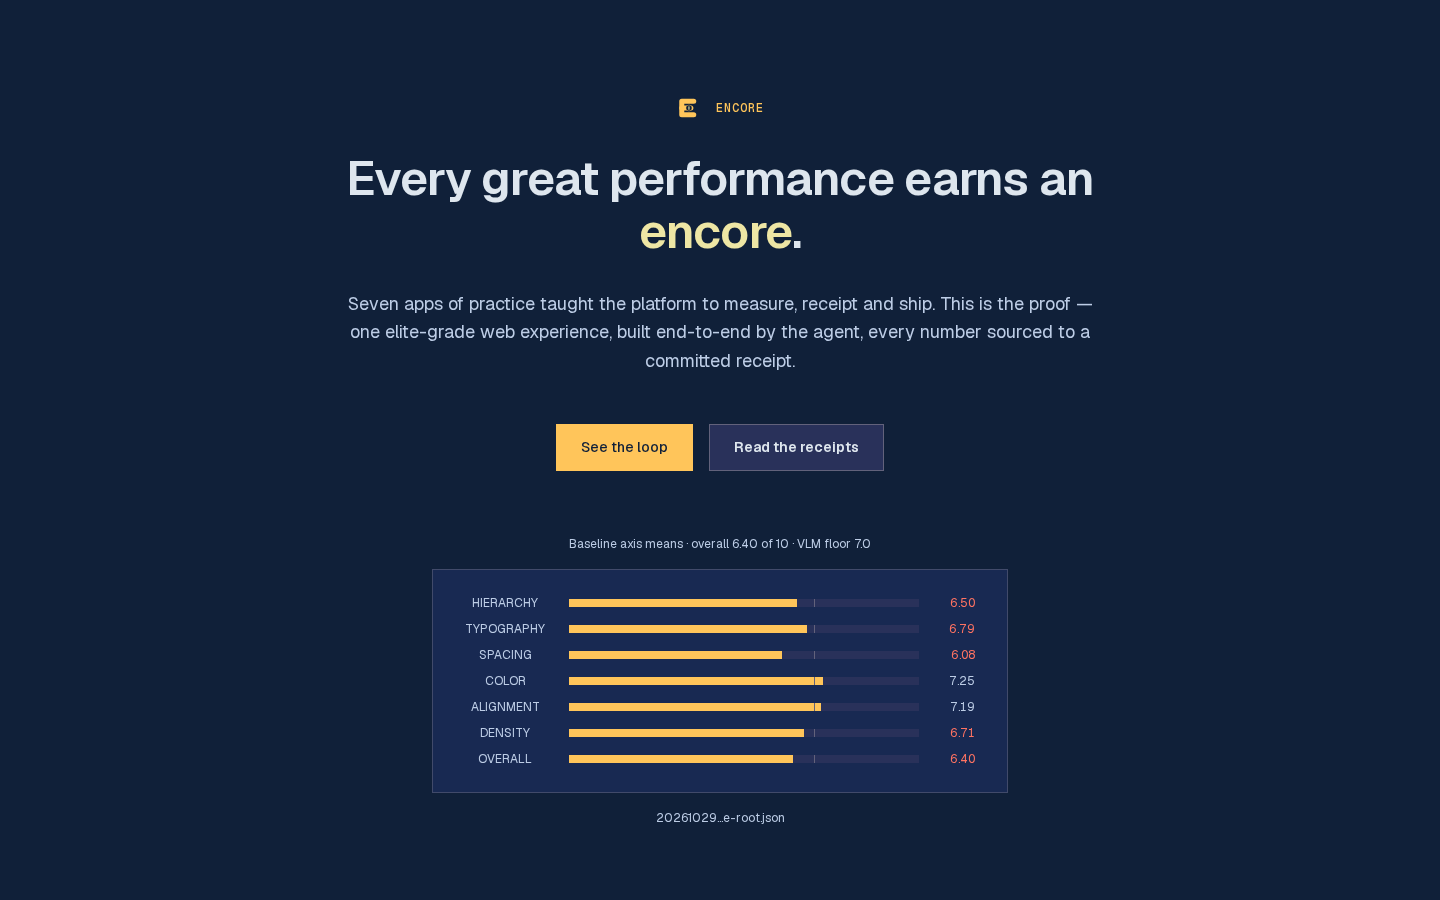
Baseline axis means · overall 6.22 of 10 · VLM floor 7.0
HIERARCHY
6.50
TYPOGRAPHY
6.79
SPACING
6.08
COLOR
7.25
ALIGNMENT
7.19
DENSITY
6.71
OVERALL
6.40
20261029…e-root.json

The Baseline

The receipt before the fix

The critic's first look at the landing page — the baseline it measures against, and the two gates it misses.

receipt · baseline20261029…e-root.json
6.40FAIL
6.40Overall20261029…e-root.json
23Distinct font sizes20261029…e-root.json
32.7%Off-grid spacing20261029…e-root.json
0Contrast violations20261029…e-root.json

11 gates

  • contrastViolations0/ 0PASS
  • fontSizes23/ ≤ 8FAIL
  • offGridPct32.7%/ ≤ 15%FAIL
  • headingSkips0/ ≤ 0PASS
  • missingAlts0/ ≤ 0PASS
  • mobileOverflow0/ ≤ 0PASS
  • fcpMs276/ ≤ 1800PASS
  • lcpMs276/ ≤ 2500PASS
  • cls0/ ≤ 0.1PASS
  • tbtMs61/ ≤ 200PASS
  • vlmAxes5 under/ floor 7UNDER

7 VLM axis means

HIERARCHY
6.50
TYPOGRAPHY
6.79
SPACING
6.08
COLOR
7.25
ALIGNMENT
7.19
DENSITY
6.71
OVERALL
6.40
The seven VLM axis means from the baseline receipt
AxisScore
HIERARCHY6.50
TYPOGRAPHY6.79
SPACING6.08
COLOR7.25
ALIGNMENT7.19
DENSITY6.71
OVERALL6.40

Provenance · 20261029…e-root.json

The Loop

A measured critique loop, receipted

Six steps, run by the critic. A run without a receipt never counts — every number on this page traces back to one.

1/6

build

Next builds /encore — the app is the surface, and it must build clean before the critic can audit it.

artifact: `next build` exit 0

  1. build — Next builds /encore — the app is the surface, and it must build clean before the critic can audit it. Artifact: `next build` exit 0
  2. capture — The Playwright lane shoots 1440×900 desktop + 390×844 mobile at every band. No shot, no score. Artifact: `shots/<route>/` PNGs
  3. audit — The objective audit runs on the captured DOM: 11 gates (font sizes ≤ 8, off-grid ≤ 15%, contrast 0, overflow 0, …), computed per device. Artifact: `audit.{desktop,mobile}` JSON
  4. critique — The VLM critiques the shots against the seven axes — hierarchy, typography, spacing, color, alignment, density, overall. Each miss is a named, receipted line. Artifact: `critiques[]` + 7-axis scores
  5. fix — The agent fixes the named misses — the F-ledger grows, the pre-push checklist gains whatever it was missing. Artifact: commit + F-ledger entry
  6. re-score — The loop runs again on the new build. A run without a receipt never counts — the new receipt is the only thing that proves the fix moved the number. Artifact: new receipt in `critiques/`

The tool that owns each step: design_critic.mjs runs build → capture → audit; the VLM runs critique; the agent runs fix; the re-score is the next receipt.

The Iterations

Before and after, receipted

The landing baseline versus the final build — five receipts, one per run. Drag to compare the two hero shots; every number on this band is computed from the seed, and every seed constant carries its receipt. The append-clean invariant means a new iteration receipt changes this band with zero code edits.

Drag to reveal the final build over the landing baseline. Keyboard: ←/→ step 10.

Landing baseline, 1440×900 — 6.40 overall, 23 distinct font sizes, 32.7% off-grid; fontSizes and offGridPct gates FAIL (receipt: benchmarks/website-excellence-round/critiques/20261029-145746-baseline-root.json)Encore final (iter3), 1440×900 — 6.22 overall, 6 distinct font sizes, 0% off-grid, all objective gates passing (receipt: benchmarks/website-excellence-round/critiques/20261029-170148-iter3-encore.json)
BEFORE · baseline · 6.40
AFTER · iter3 · 6.22
before · landing baseline · receipt · baselineafter · final build · receipt · iter3

The trajectory — one receipt per run

  • baseline14:57:46 UTCVLM 6.40FAIL: fontSizes, offGridPct8/11 gatesreceipt · baseline
  • iter016:12:16 UTCVLM 6.27FAIL: mobileOverflow9/11 gatesreceipt · iter0
  • iter116:29:27 UTCVLM 6.00FAIL: mobileOverflow9/11 gatesreceipt · iter1
  • iter216:53:27 UTCVLM 6.00FAIL: contrastViolations9/11 gatesreceipt · iter2
  • iter317:01:48 UTCVLM 6.22all objective gates PASS10/11 gatesreceipt · iter3

Honest read: the objective discipline gates transformed — 23 font sizes → 6, 32.7% → 0% off-grid — while the VLM overall (6.40 → 6.22) sits within a single judge's variance band. The receipts, not this band, are the evidence.

Axis-by-axis delta (iter3 − baseline)

Score delta table between baseline (6.40) anditer3 (6.22), axis by axis
Axis20261029…e-root.json20261029…encore.jsonΔ
HIERARCHY6.506.32−0.18
TYPOGRAPHY6.796.26−0.53
SPACING6.086.00−0.08
COLOR7.256.65−0.60
ALIGNMENT7.197.12−0.07
DENSITY6.716.74+0.03
OVERALL6.406.22−0.18
GATES PASSING8/1110/11+2.00

20261029…e-root.jsonΔ20261029…encore.json

  • HIERARCHY6.50 → 6.32−0.18
  • TYPOGRAPHY6.79 → 6.26−0.53
  • SPACING6.08 → 6.00−0.08
  • COLOR7.25 → 6.65−0.60
  • ALIGNMENT7.19 → 7.12−0.07
  • DENSITY6.71 → 6.74+0.03
  • OVERALL6.40 → 6.22−0.18
  • GATES PASSING8/11 → 10/11+2.00

Provenance · 20261029…encore.json

The Tools

Two tools, built this round

The design critic and its calibration fixture — the two instruments that make the loop's numbers real.

design_critic.mjs

The critique loop: build → capture → audit → VLM critique → receipt. Every number on this page traces to a run of this script.

headline6.40 baseline, verdict FAIL — 23 font sizes > 8, 32.7% off-grid > 15

receipt · design-critic

design_critic_calibration.html

Known-bad fixture proving the critic discriminates: 11 ad-hoc type sizes, arbitrary odd spacing, sub-AA greys, an h1→h4 skip, an alt-less image.

The critic scores the known-bad fixture 1.50 vs the real page 6.40 — a 4.9-pt separation proves it discriminates, it does not rubber-stamp.
Known-bad fixture
1.50
Real baseline
6.40

receipt · calibration-fixture

Provenance · 20261029…d-root.json

The Failures

Every failure became a benchmark

The round's P0s and P1s, ledgered with their root causes, their fixes, and the receipt that proves each one is closed.

  • F10

    Landing page.tsx + route.ts shipped at the same segment — main un-buildable, CI red, Vercel deploy failed, production stale.

    CLOSEDJSON twin moved to /nocturne/api/public-status/[slug]/route.ts; build green; pre-push checklist (typecheck + lint + test:unit + build) adopted.

    fix-ref: docs/website-excellence-session.md CP0 — · commit 3c4cf87

  • F11

    Four lint errors shipped to main — the nocturne round's closeout skipped `bun run lint` before pushing.

    CLOSEDopenIncident hoisted above reopen; two require() calls lifted to top-level import; lint gate added to the pre-push checklist.

    fix-ref: docs/website-excellence-session.md CP0 — · commit 89535c6

Every failure on this ledger became a benchmark that the loop runs every time. A new failure appends to the array — the UI renders it with zero code change.

The Finale

The question the round set out to answer

The program's success question:

“Can a measured, receipted critique loop take a page from FAIL to PASS, and prove it?”

Current answer · receipt · iter3Not yet — the loop is mid-flight at 6.22 overall (iter3).The answer flips when the next receipt lands with passed: true — zero code change.
Back to the galleryRead the session log
Encore — the Website Excellence showcase · gallery app #8 · 6.22 overall · receipt · baseline