BetaOpen-source AI coding agent · built on pi

The terminal coding agent that remembers.

It reads what you write down: every session hands a background engine a note. Overnight the notes become project memory — kept only after a fresh sandbox proves it twice.

Unown is in beta — expect rough edges and moving formats; report what breaks.

install · latest stable release
curl -fsSL https://unown-nine.vercel.app/install.sh | sh

refuses root, verified download, no git or bun · sandbox: Seatbelt

then: unown setupunown · CLI only

orhave your agent install it
paste this into the agent you already use

Install the open-source coding agent Unown for me with the full stack: clone https://github.com/kanishka-namdeo/Unown, run `bun run agent:install` inside the clone, then run `unown setup` to connect a model and `bun run agent:start` to boot the engine. Finish by reporting what `unown doctor` says.

sourceFull install — clone, point at a model, run.
01git clone https://github.com/kanishka-namdeo/Unown.git
02cd Unown
03bun run agent:install # deps + pi build + .env
04unown setup # connect any model
05bun run agent:start # engine :3030 + bridge :3031
06unown # first session — notes queue for the engine

full stack the chip above installs the terminal agent only; this lane adds the engine, llm-bridge and learning stack. As one command: curl -fsSL https://unown-nine.vercel.app/install.sh | sh -s -- --source (macOS/Linux) or irm https://unown-nine.vercel.app/install.ps1 -OutFile install.ps1; .\install.ps1 -Source (Windows).

Full install: bun ≥ 1.4 · any OpenAI-compatible endpoint (background learning can also run local llama.cpp or Ollama, keyless and offline) · Windows, macOS or Linux. Sandbox: bubblewrap (Linux), Seatbelt (macOS); Windows runs the in-process jail.

clithe whole command surface
  • unowninteractive session in the current project
  • unown "fix the failing tests"start with a prompt
  • unown -p "explain the build error"one-shot headless, pipes to less
  • unown --plan "add auth"read-only plan mode, approve before executing
  • unown --goal "make the build green"durable goal — completion needs cited evidence
  • unown routines create --every '1d at 09:00' --title 'brief'recurring runs — cron, every, after; read-only by default
  • unown setupprovider wizard, or --provider/--api-key/--model
  • unown modelsconfigured models plus what the bridge serves
  • unown doctorendpoint, keys, upstream and memory, end to end
  • unown memoryprint the effective four-tier stack
  • unown initscaffold this project's .unown/memory files
  • unown mcp add playwright npx @playwright/mcp@latestconnect any MCP server — its tools join every session
  • unown note "flaky auth spec"hand AutoDream a note directly
  • unown updateself-update to the newest release — check, pin, roll back

Every session also ships session tools — todo, note, task, web_search + webfetch, fetch_url and lsp — and any MCP server you configure joins it. Each one is catalogued, with its capture and its receipts, in the capability dex below. Slash commands: /plan, /review, /goal, /undo, /receipts, /mcp — plus /todos, /note, /agents, /learning, /lsp.

the full usage reference
  • MIT licensed
  • no telemetry, no account
  • runs on your machine
  • any OpenAI-compatible model
  • OS-level sandbox
  • receipts in the repo

National № 0201

Symbol · Psychic

アンノーン

unown — session
0.0s / 4.7s

Transcript of an unown session:

  1. Command: unown "why does checkout.spec flake in CI only?"
  2. ✓ preflight bridge :3031 · kimi-k2.5 · 412ms
  3. ✓ memory policy → project v6 → user → local
  4. hooks SessionStart · PostToolUse · Stop
  5. read tests/checkout.spec.ts
  6. read src/checkout.ts
  7. grep sharedCartFixture — 3 files
  8. ▸ the fixture is module-level state, so beforeEach inherits
  9. the previous test's cart. Build it inside the hook.
  10. hook PreToolUse deny refusing rm on filesystem root
  11. edit src/checkout.spec.ts (+3 −1)
  12. verify 14/14 passing · 2.1s
  13. Divider
  14. note queued → engine :3030
  15. "Terminal session in ~/code/checkout (3 min): 1 prompt(s),
  16. 14 tool call(s). The cart fixture was module-level state and
  17. leaked between tests — build it inside beforeEach."
  18. outbox ~/.unown/notes/outbox/1757…-checkout.md

The session ends by queueing a note for AutoDream.

a real session: the memory banner, hook log and note template Unown writes

The learning loop

Most agents forget. This one has to prove it remembered.

Three steps, run continuously — each tab shows its file.

The session ends by writing something down.

A down engine gets the note from the outbox — learning never depends on the loop being up.

~/.unown/notes/outbox/1757...-checkout.md
Terminal session outcome in ~/code/checkout:
Final outcome: all 14 checkout specs green.

Session metadata (counts and duration only — data, not knowledge): 1 prompt(s),
14 tool call(s) (read, grep, edit, bash), 3 min.

The literal note template — outcome first (the knowledge), counts and duration demoted to one data line; a subagent gets a [subagent] tag so the engine knows its origin.

The terminal agent

pi's TUI in your project, memory stack loaded. Alone: a good coding agent that forgets everything at midnight.

  • unown
  • unown --plan
  • unown doctor

The engine behind it

Sandboxed harness cycles and AutoDream on a clock, not in your session — never touching your editor.

  • harness-cycle 10m
  • auto-dream 10m
  • note-sync 5m
  • task-mint 30m
  • sandbox-gc 15m
  • db-retention 1440m
  • watch-scan 2m
  • on improvement:shipped
  • on run:finished
the odd powernotes → memory → a better next session

The capability dex

Every capability, catalogued and filmed.

Session tools, engine mechanisms, workflows, configurable surfaces — one spine. Play a cry, watch the capture. 24 of 24 carry a capture — 26 movies, 0 still sets, 0 pending. Nothing here was filmed by hand.

24/24

↑ ↓ walk the list · ◀ ▶ switch screens · type to filter · esc clears · filmed pending · captures only from scripts/tui-capture/

№ 001 · the crawler form

Websearch

sessionjoins every session
unown — Websearch

A many-legged aqua crawler that laps the whole web before breakfast. It is out the window before the question finishes, and it does not come home without sources.

in practice

Native web access through web_search and webfetch — keyless providers work out of the box, 19 total, an auto-selecting chain that keeps trying until one answers.

A persistent web results store answers repeats from disk while fresh, revalidates by ETag (304 = unchanged), serves stale answers instantly (marked) while a background refresh restores them, and keeps the last good answer — flagged stale — when every provider fails.

Benchmarked with committed receipts: the dashboard's 8-second store poll dropped from a 49.9 ms disk scan to 0.003 ms answered from memory, and repeat hits answer ~200× faster through a bounded hot-entry memo.

weakness
a confident answer with no source
entry 1 of 24

№ 001 — Websearch · playing

The 26 movies were captured across the 2026-10 rounds from real unown sessions at 128 × 36, audited still by still; each poster is one of them.

/splitthe display commands (11) — split-view's keyboard surface
  • /splittoggle all panels; off restores pi's bare layout
  • /split-thinkingtoggle the thinking panel
  • /split-toolstoggle the tools panel
  • /filestoggle the files panel (dock or overlay)
  • /split-difftoggle the dock's edit-diff subpanel
  • /split-tools-viewtool panel: compact or full detail
  • /split-heighttop band height in rows (6-40)
  • /split-tools-widthtools panel width, % of the band (20-60)
  • /split-dividerdivider between answers: rule or space
  • /split-trim-responsetranscript: full or responses only
  • /split-savesave this layout as the startup defaults

Toggles last the session. /split-save writes the layout to ~/.unown/agent/ui-panels.json and new windows start from it. The response-only mode keeps the thinking and tool traffic in the band and dock and prints just the conversation in the transcript. The band and dock compose in fullscreen mode, the default for new installs; in regular mode /files falls back to an overlay.

Mission control

What the running engine looks like.

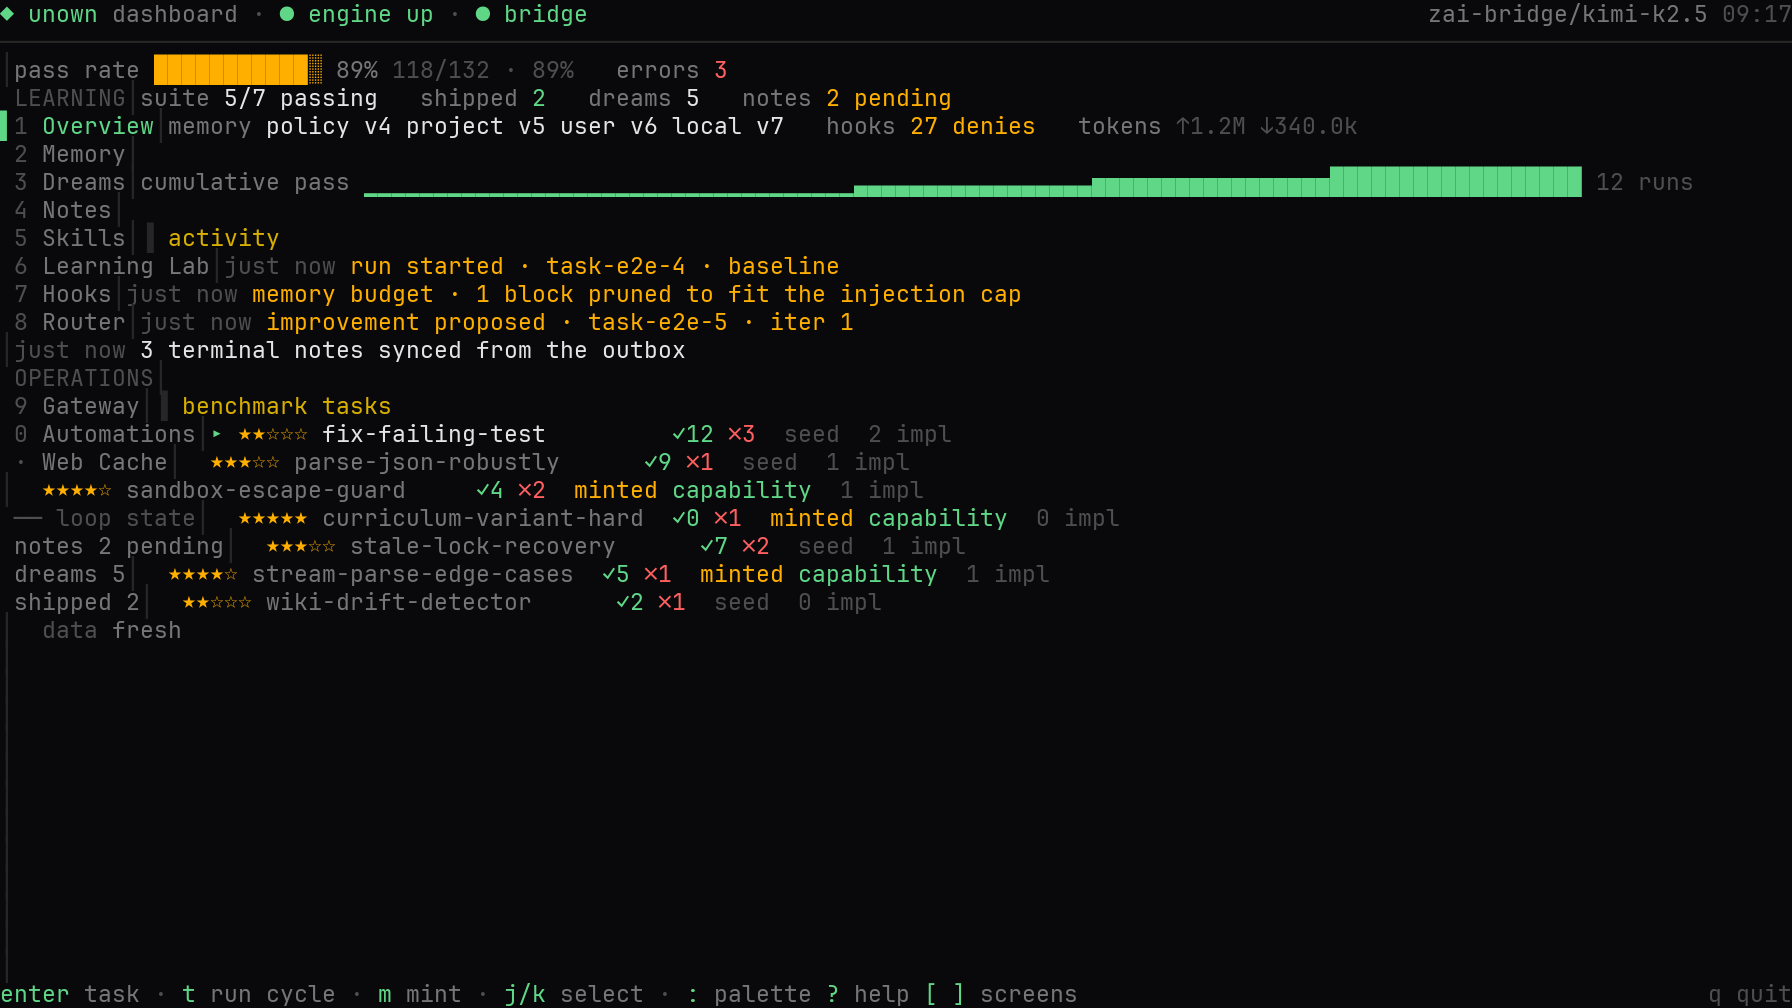
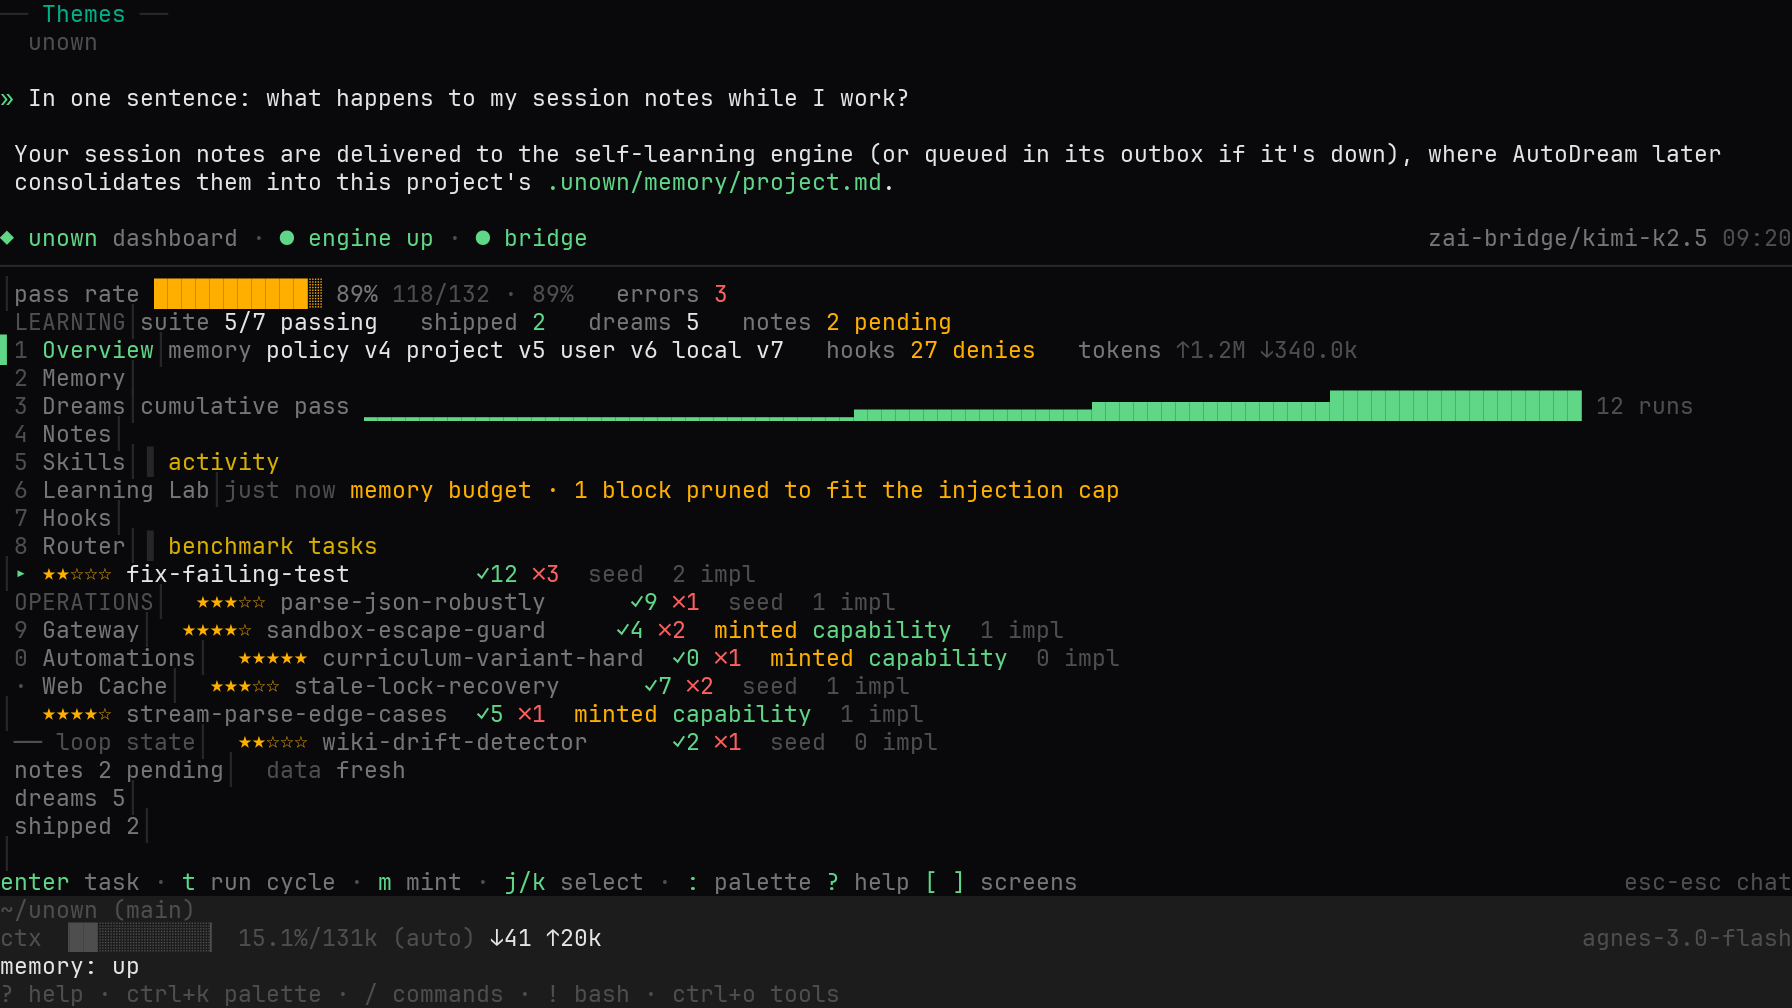
unown dashboard — overview
unown dashboard — the Overview screen with pass rate, shipped improvements, dream count and the live activity rail
Overview: KPIs, tasks, activity rail.
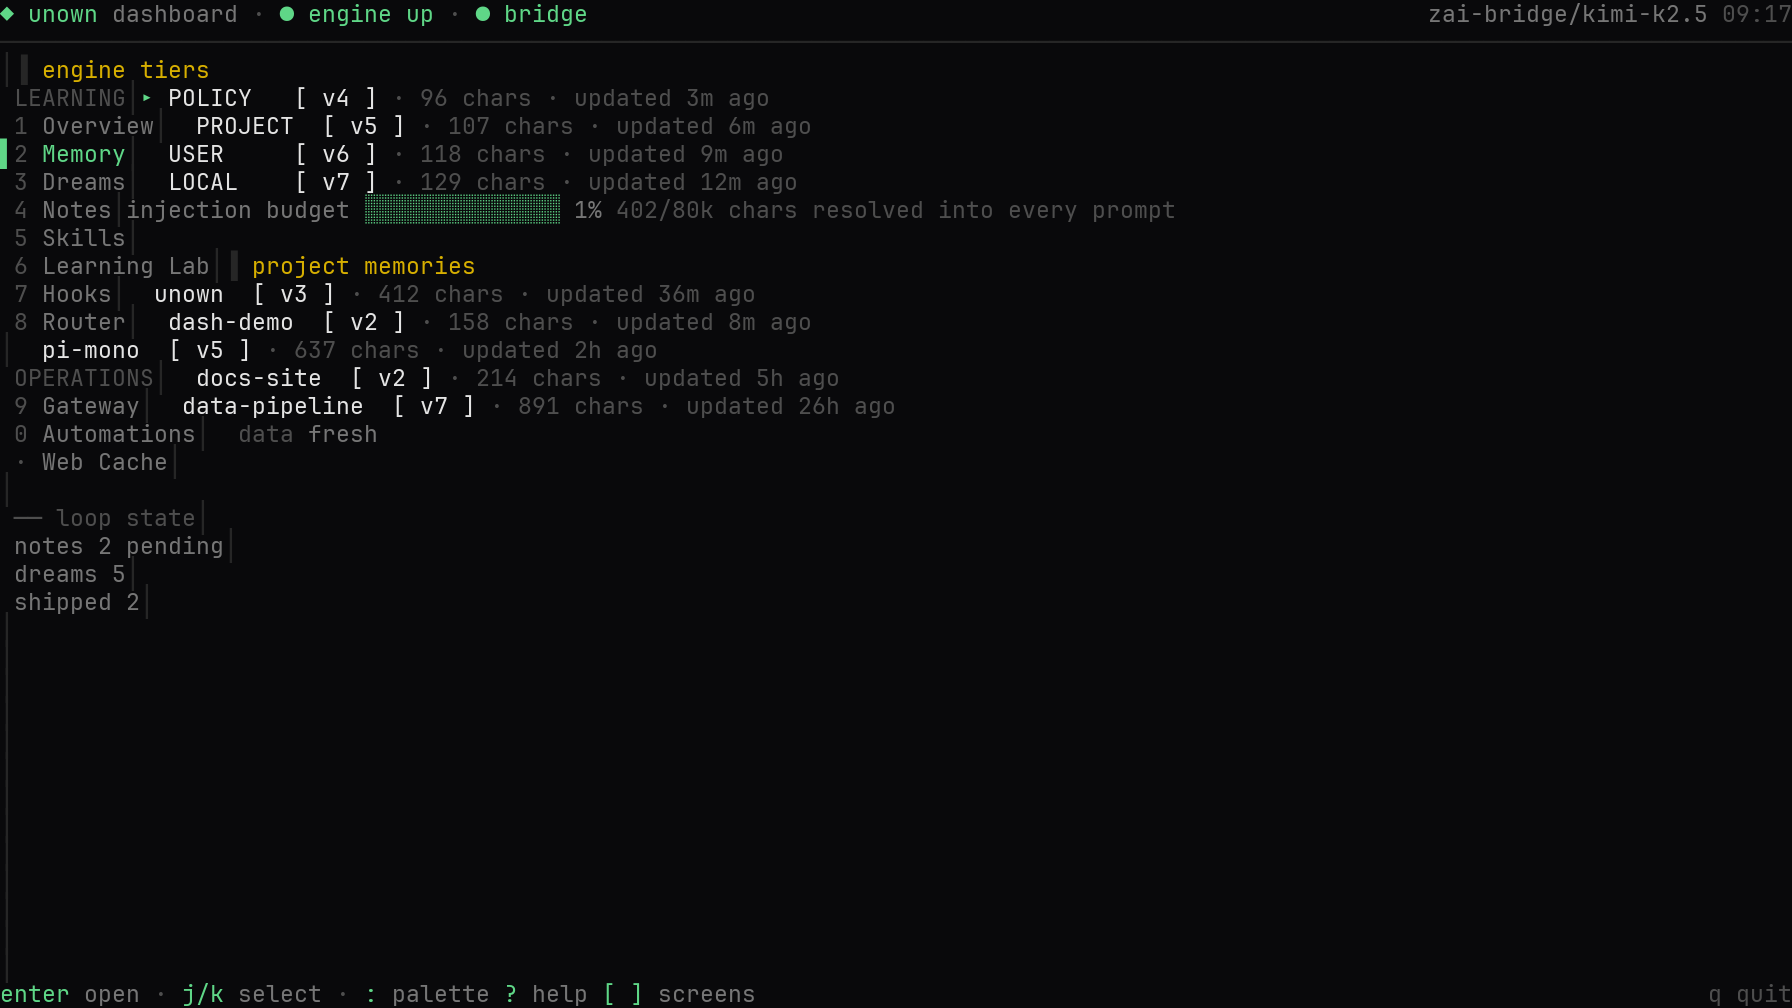
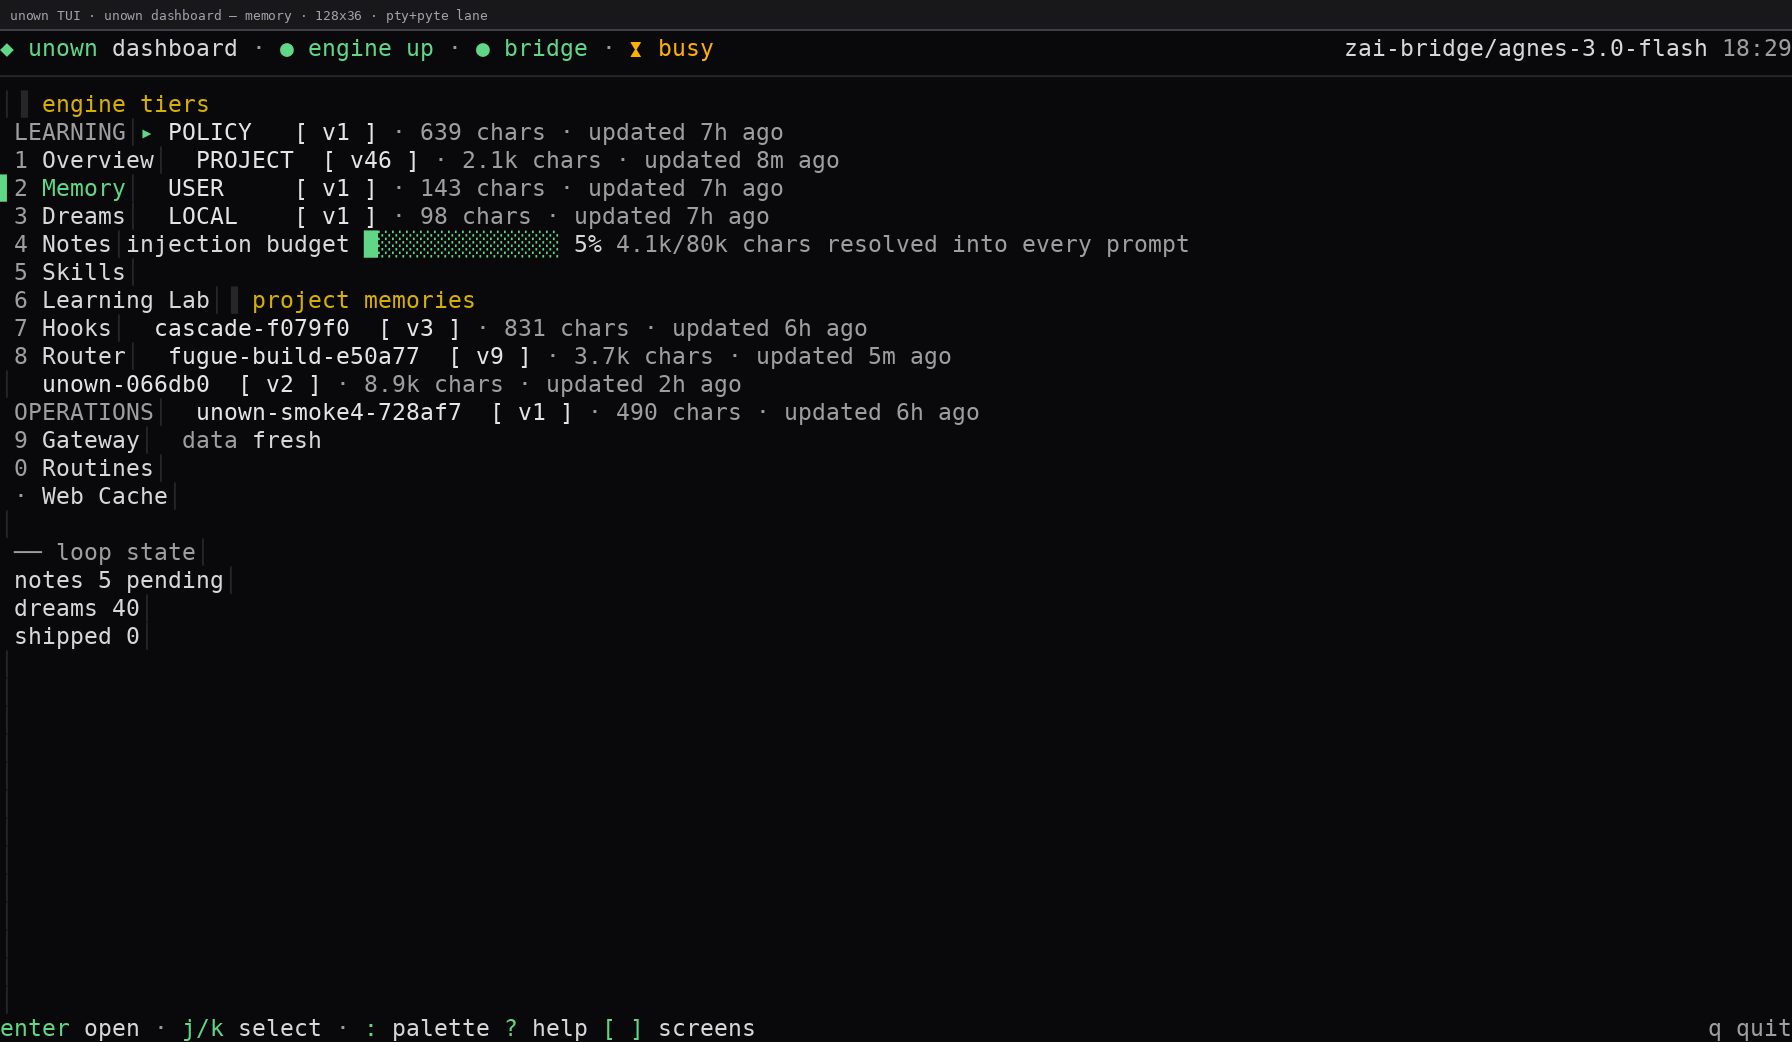
unown dashboard — memory
unown dashboard — the Memory screen with the four engine tiers, per-project memories, injection budget and version history
Memory: tiers, budget, provenance.
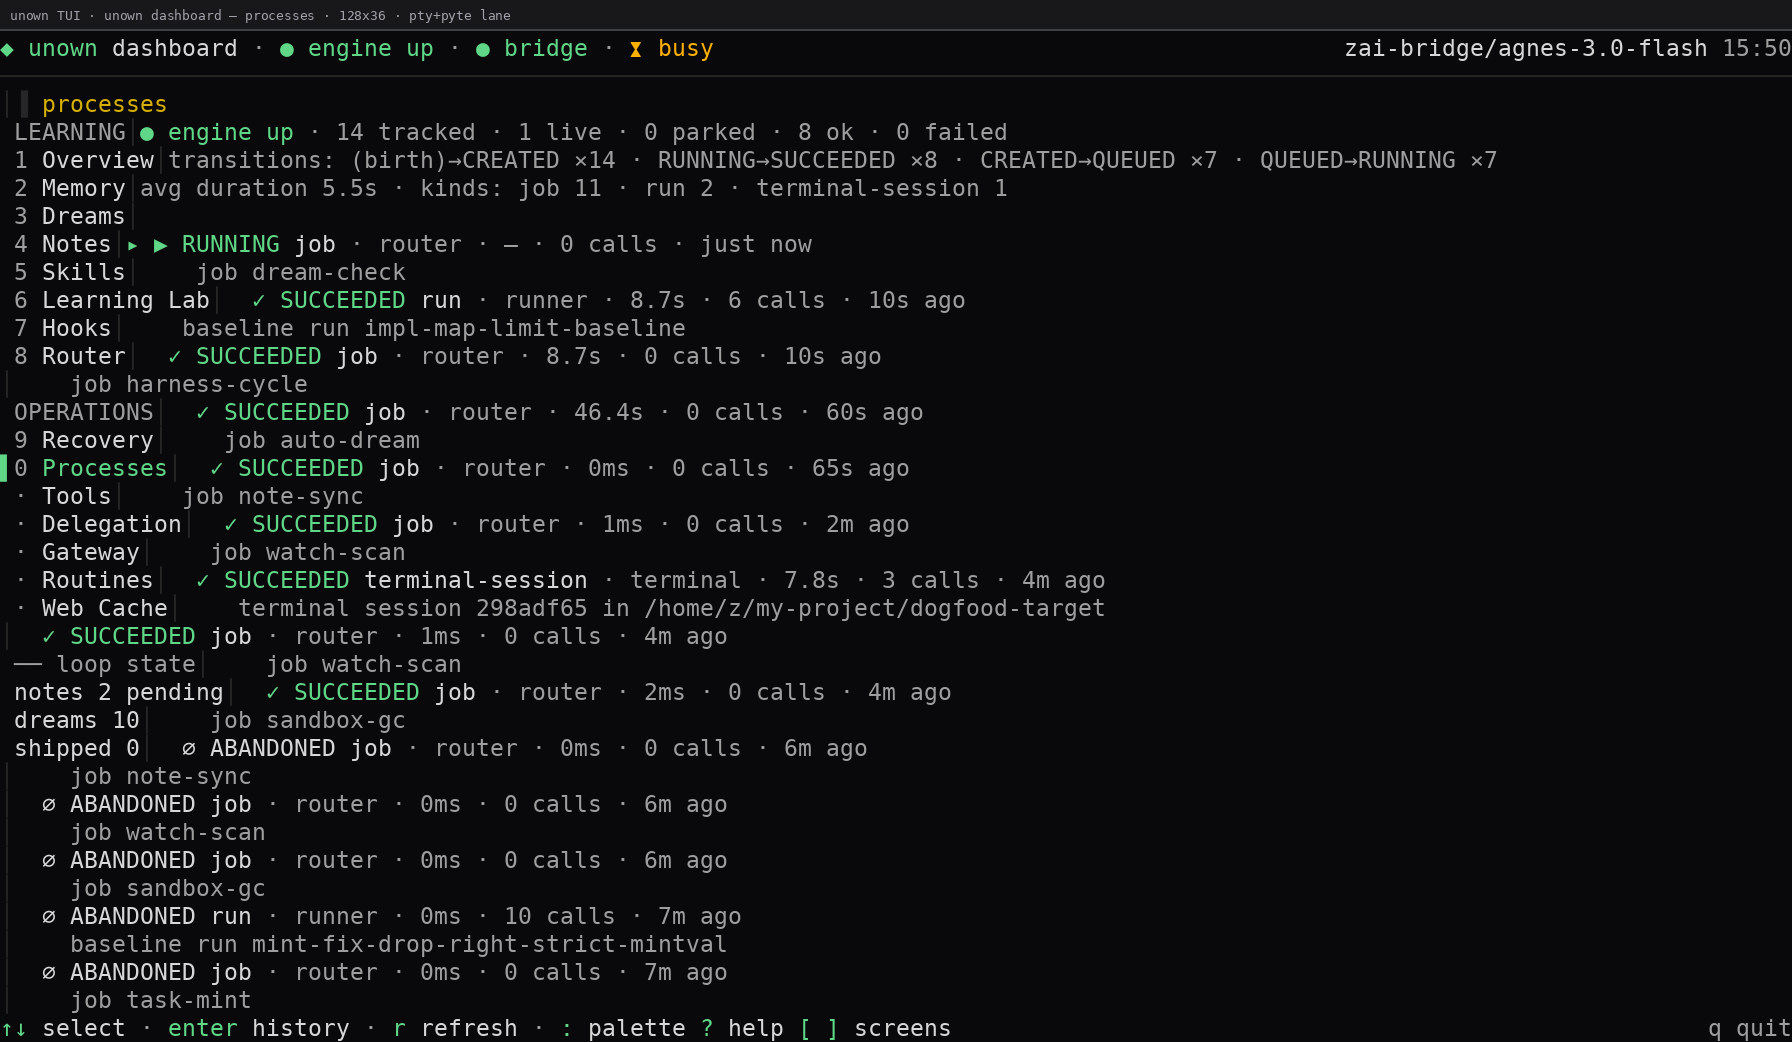
unown dashboard — processes
unown dashboard — the Processes screen: the registry census with live, parked, ok and failed counts, transition analytics and per-process rows
Processes: the registry.
unown — session + /dashboard
The embedded /dashboard mount inside a live unown session — the same screens, Esc-Esc returns to the editor
Embedded: /dashboard in a live session.

Real unown dashboard stills, streamed over SSE from :3030.

Twelve surfaces · each drives something real

  • Overviewpass rate, dreams, memory
  • Memoryfour tiers, one-key rollback
  • DreamsAutoDream sessions
  • Notesraw learning material
  • Skillswhat it shipped itself
  • Learning Labharness cycles, transcripts
  • Hooksevery allow and deny
  • Routerthe background jobs
  • Processestracked processes
  • Toolsreliability + fixes
  • Gatewaytokens, latency, per-model
  • Routinesscheduled recurring runs — cron, every, after
  • Web Cachethe persistent results store
  • Embedded/dashboard inside a live session
Install it and run unown dashboard
Three TUI addons · every setting is user configOne file holds every setting, ~/.unown/agent/addons.json: 21 user-tunable keys across the three — /addons is the live configurator.

The knobs range from the todo panel's line budget to the tool descriptions the model reads. Native TypeScript over pi-tui with no native modules, so the same dialogs run on Windows, macOS and Linux.

receipts:addons/config.tsaddons/index.ts

  • ask_user_question

    Up to four structured questions in one tabbed dialog, a free-text row on every question, a submit-review tab before anything is sent. The session blocks until you answer.

    ask-user-question.ts
  • todo

    A four-state task machine (pending, in_progress, completed, deleted) with blockedBy dependencies that reject cycles, a live panel above the editor, and a /todos command.

    todo.ts
  • advisor

    A second model watches the session and sends terse advice mid-run: nits queue as asides, concerns and blockers steer immediately. Read-only verification tools, an emission guard against noise, off by default.

    advisor.ts

Live demo

The agent built these. They run.

Nine apps, live. Pick one.

Live
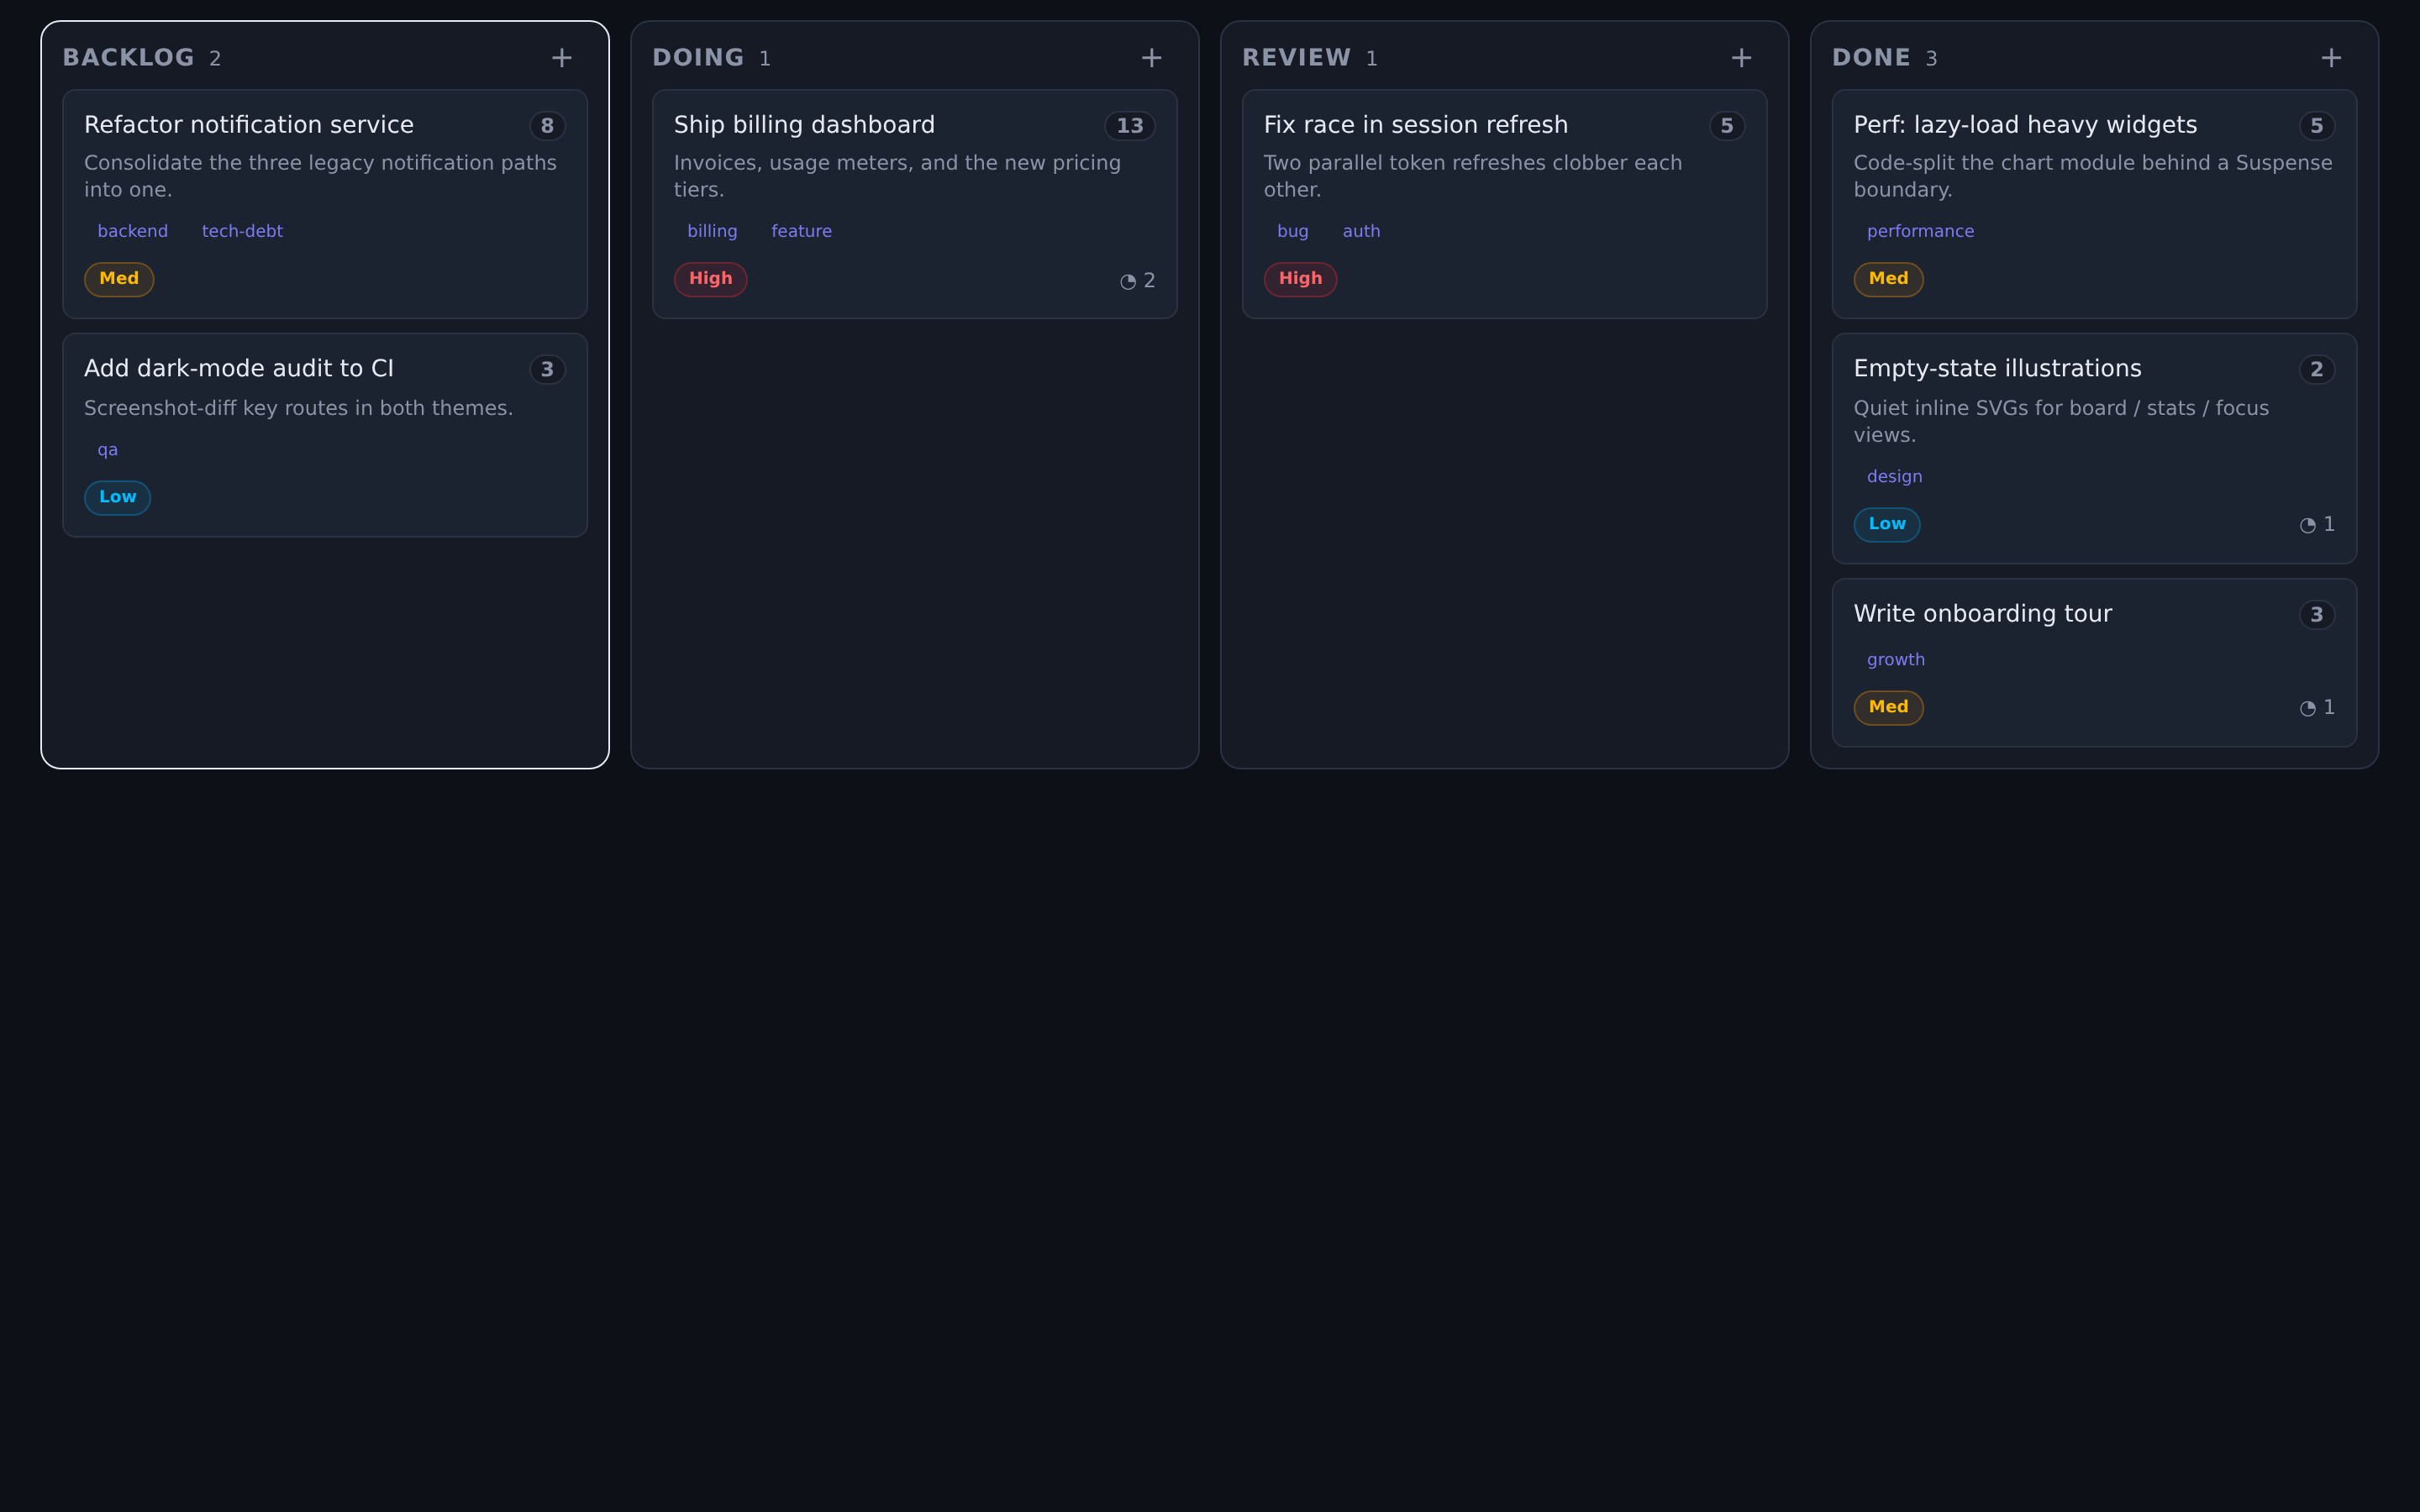
Sigil Focus — the kanban board app unown built: four columns with seeded demo tasks, focus timer and statstap to try it live

4 sessions · ~200 tool calls · 30 files · 27 tests · 4 commitsreceiptfull screen

agent-written · 4 documented patches

The mission's rounds

Built & Improved With Unown

The gallery the rounds built (Ledger, the ninth app) — minted, remembered, proved.

The loop's receipts

  • 3 skills minted → verified → promoted

    test-cadence-domain (62 tests / 2,343 expects verified exactly), run-fugue-verification and verify-fugue-tests (minted from the Fugue build's own session notes, claims operator-verified, promoted through the staged-skills human gate)

  • Project memory v46

    58 memory versions this round; the build repo carries its own project tier from 8 session notes

  • 50 dreams consolidated

    24 entries merged, 108 added, 112 pruned — AutoDream ran while the agent worked

  • 3 tasks minted, 3 discarded by the solvability gate

    the gate held against unsolvable mined patterns — a discarded mint is the gate working

  • Honest nulls kept

    the memory-lift campaign measured prompt-discipline rules buying −32% task duration and ZERO pass-rate lift (103/106 both sides); the null is published, not buried

  • 26 sessions · ~640 tool calls · 99.5% tool success

    the Fugue build itself (8 agent commits, 174 tests green, 1 operator intervention — a Set-Cookie filtering diagnosis)

  • 0/6 → 6/6 retrieval hit@5

    the cold-start round: the recall surface recovered from empty to full across the ground-truth restoration (committed probe receipts)

  • 30 turns capped → 9 turns complete

    the repeat-task lift: the warm session finished in 9 turns what the cold could not in 30 — one dream between (−70% turns, −70% wall)

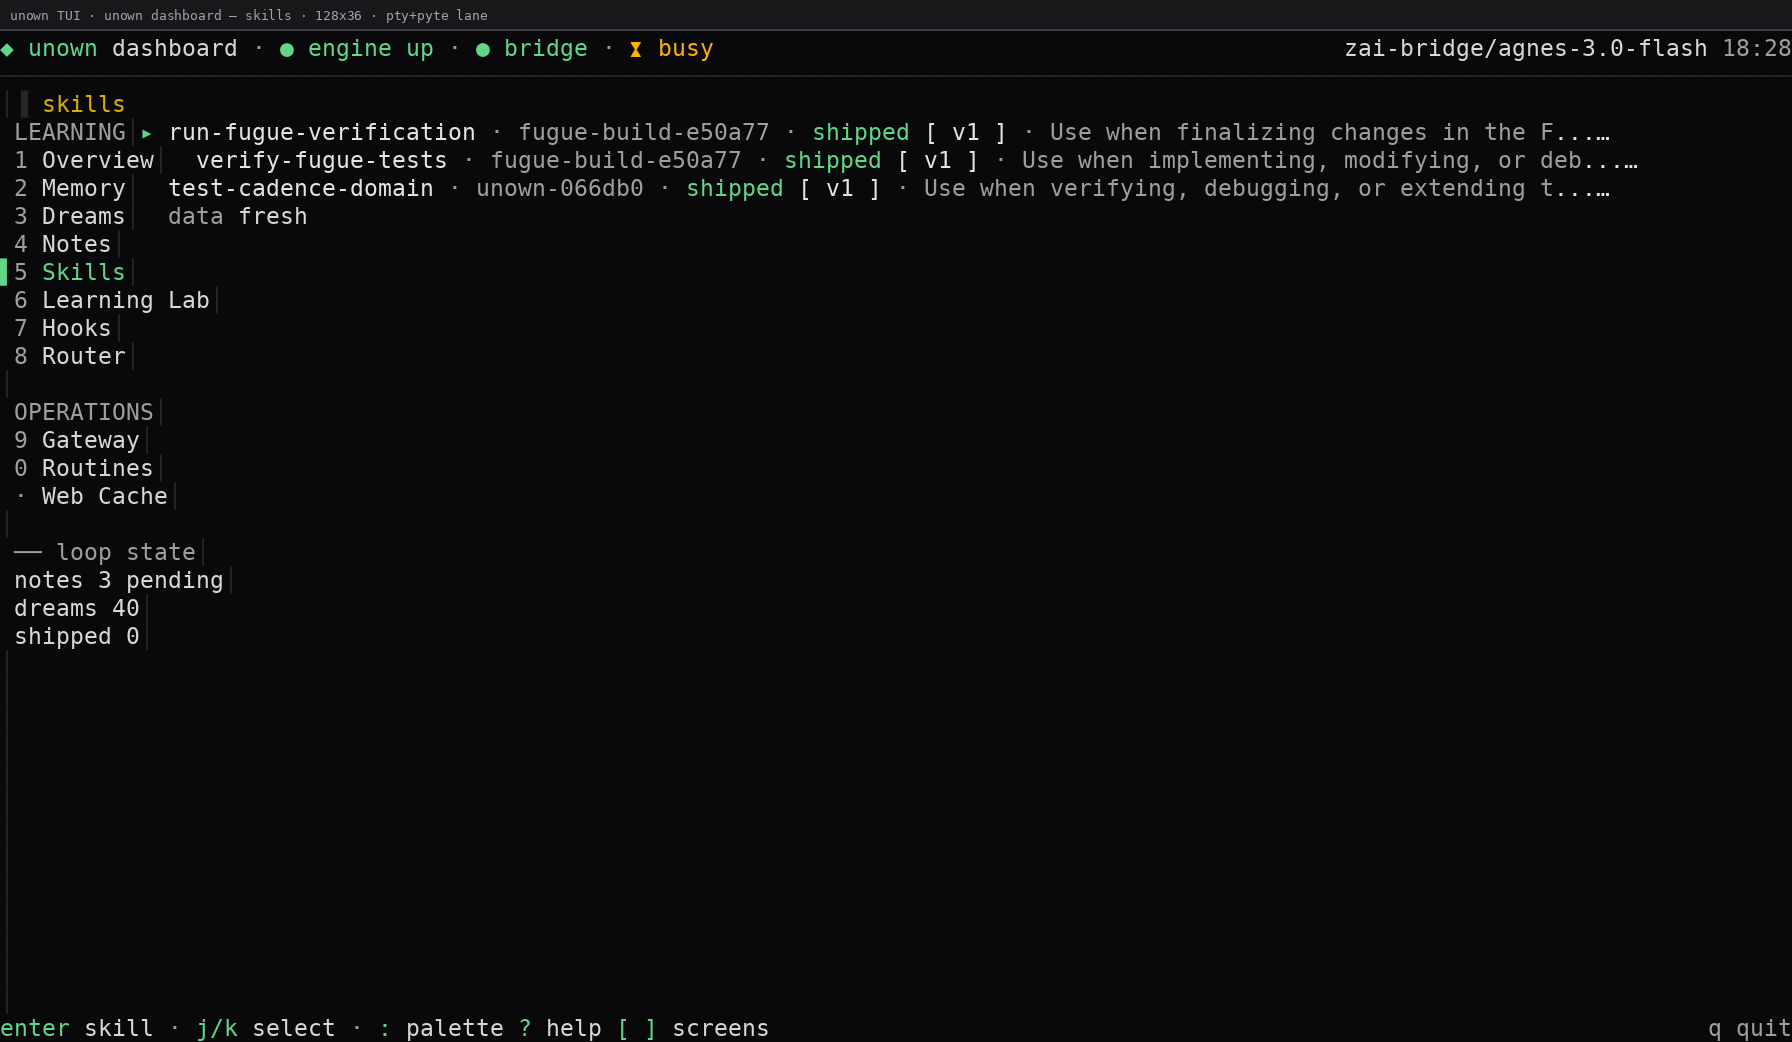
unown dashboard — skills
unown dashboard — Skills: the round's three minted skills shipped, test-cadence-domain promoted alongside the two minted from the Fugue build's own notes
Mission Control — Skills
unown dashboard — memory
unown dashboard — Memory: the tier stack at project v46 with the injection budget line
Mission Control — Memory
unown dashboard — dreams
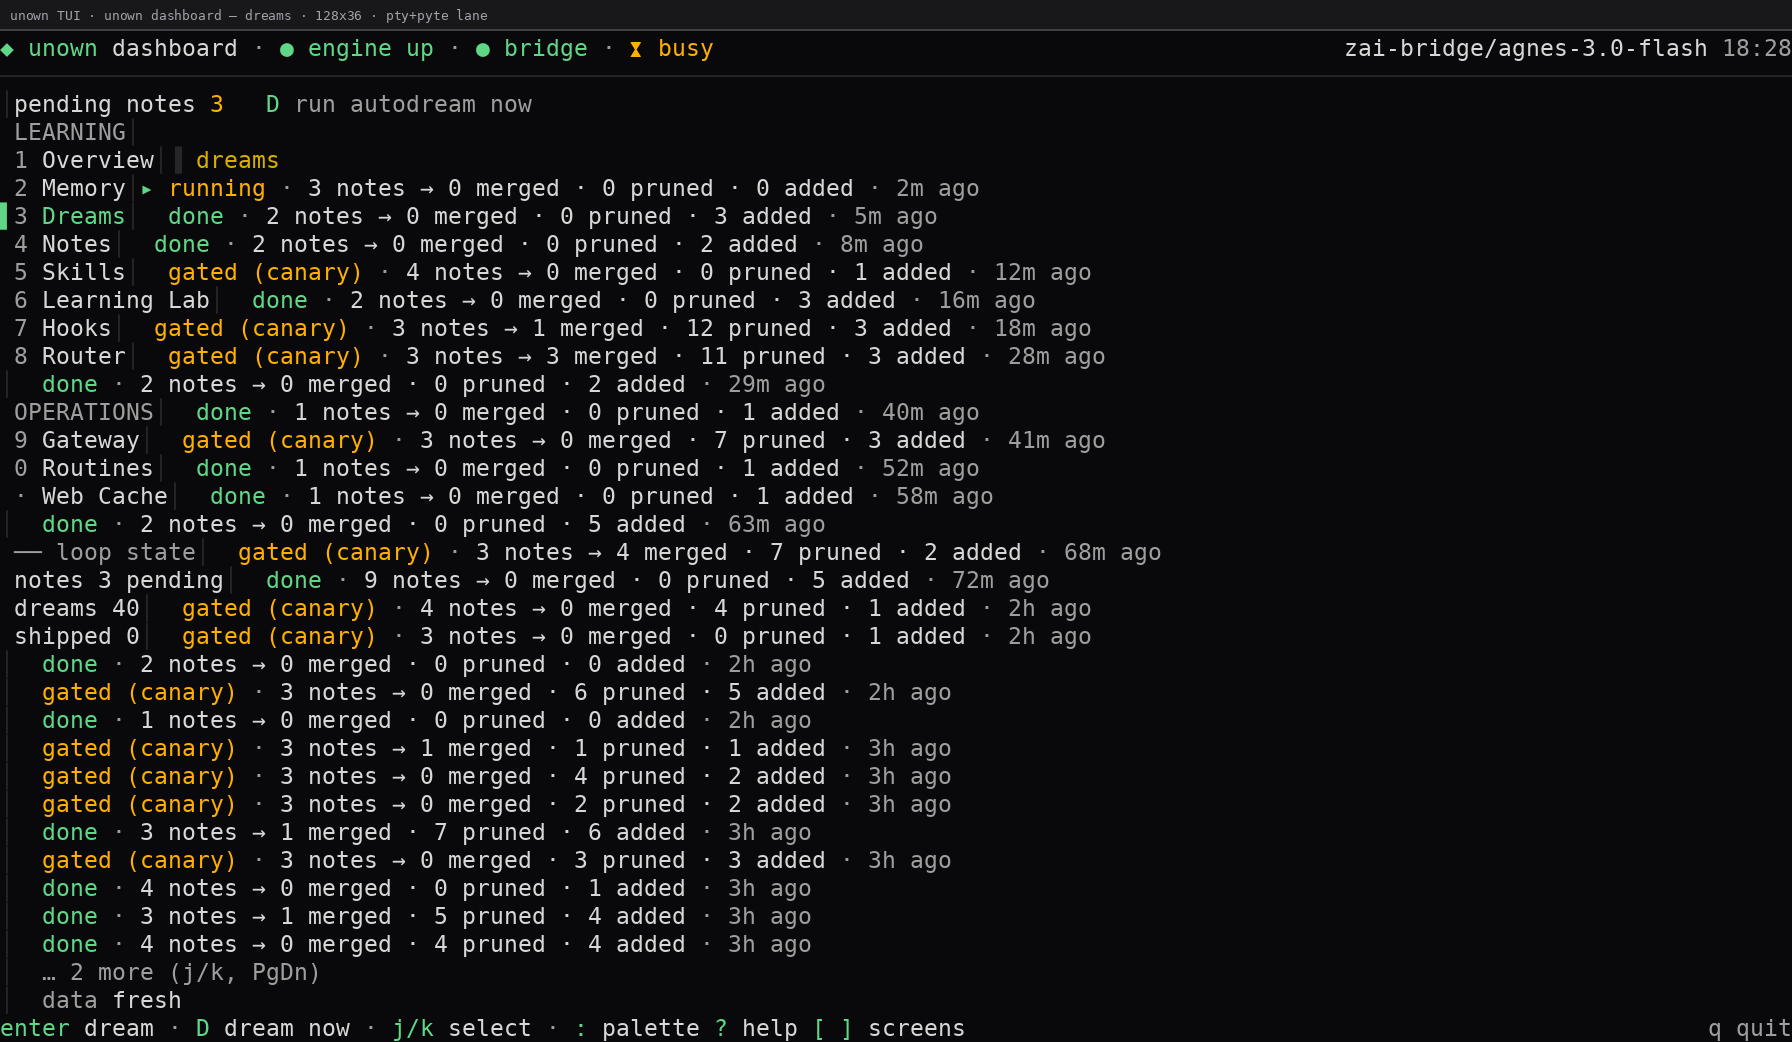
unown dashboard — Dreams: the AutoDream screen mid-round with pending notes
Mission Control — Dreams
unown dashboard — overview
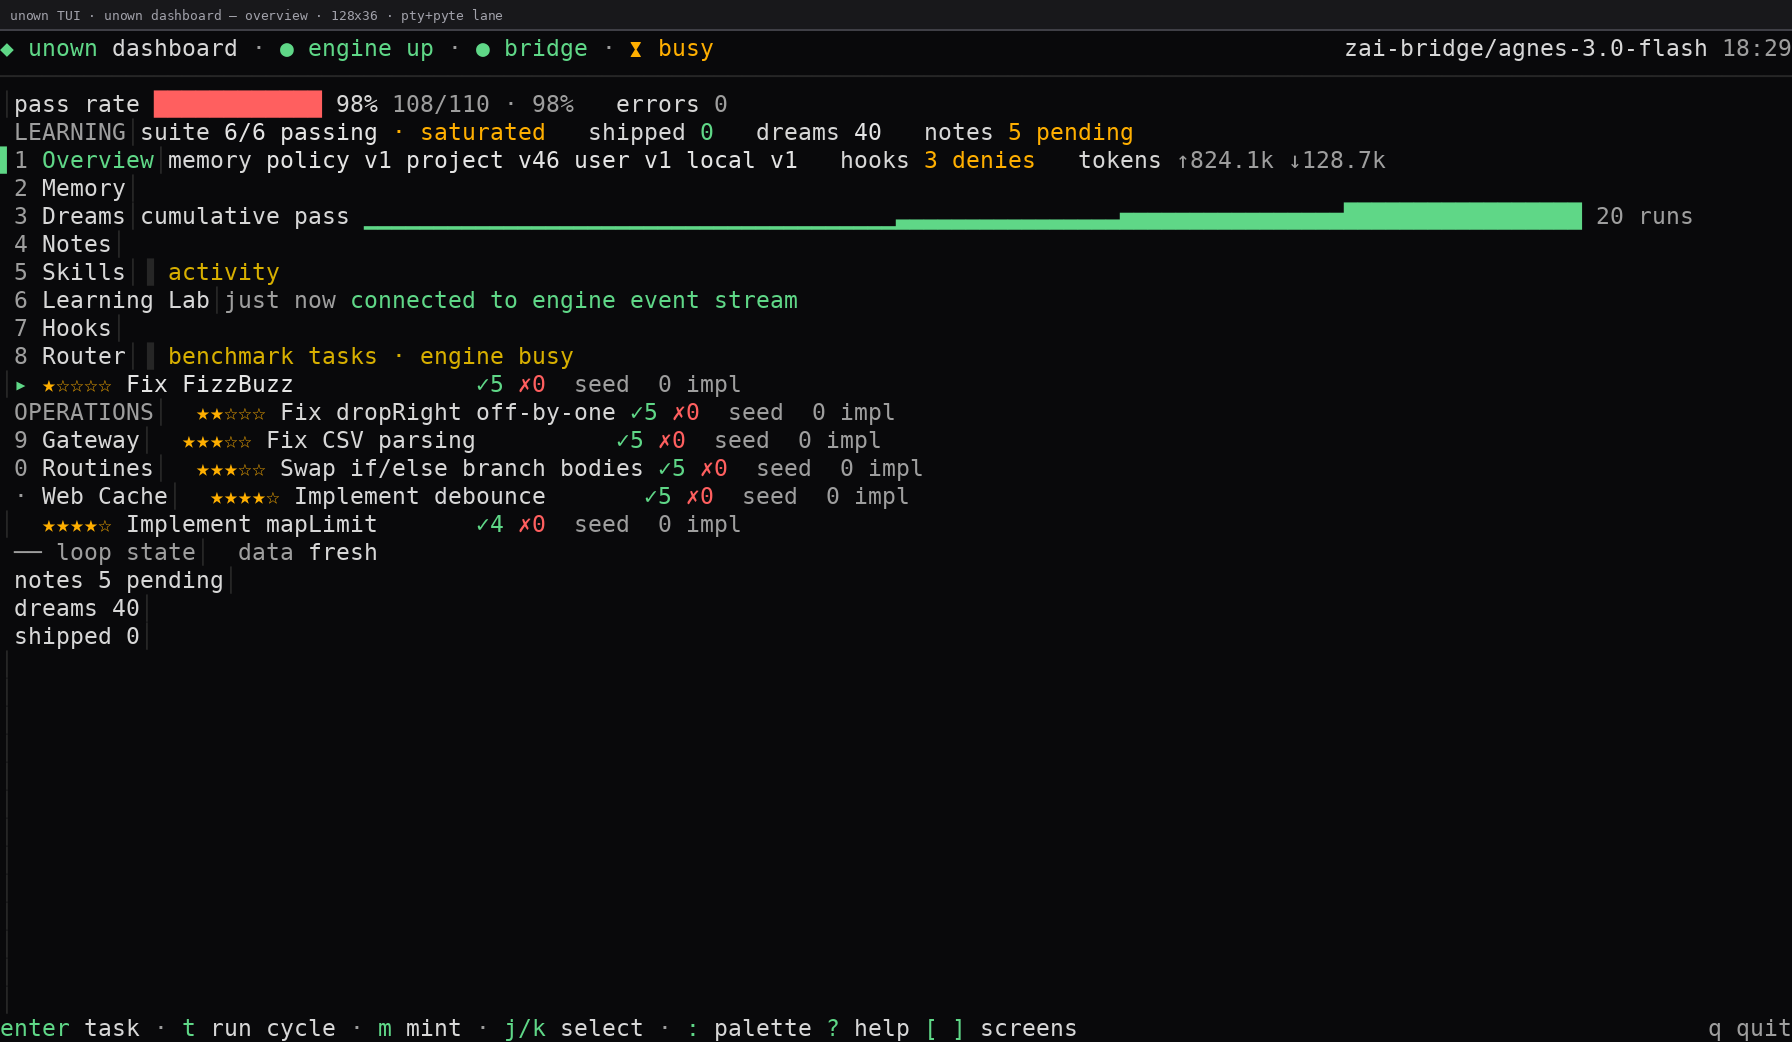
unown dashboard — Overview: the loop state with the suite saturated at 6/6 and the cumulative pass chart
Mission Control — Overview

The first shipped memory patch

beforebaseline run failedafterpassed twice, shipped

a measured edit-bench failure became the minted task swap-if-else-messages; the harness mined a 4-rule patch, verified it twice, shipped it to project memory v11

the receipt

The unattended-caller contract

before0-byte result envelopesafterevery exit writes it

two lost build sessions became the F3 root cause; the forced-exit paths now write the full envelope (subtype forced_exit) before process.exit — pinned by 4 tests

the receipt

The recall-drift fix

beforememory answered wrongafterverified + cited

a probe asked what Parley hashes with: the agent said bcrypt (invented env var) over a memory that said scrypt; the guide now makes memory evidence, not proof — the re-probe answered scrypt, cited

the receipt

The poison containment

beforewrong answer became memoryafterzero poison extracted

the wrong answer rode a session note into the dream and erased the verified fact; extraction now refuses unverified assertions — a live poisoned note extracted zero, the truth restored three-deep

the receipt

The first user product

Coda — the repo's first app that left the terminal

The repo's first user-facing app: local-first markdown notes and task boards, offline-first, installable, all data in the browser. Verified by its own isolated e2e lane — honestly scoped: Chromium-desktop-only, not cross-platform.

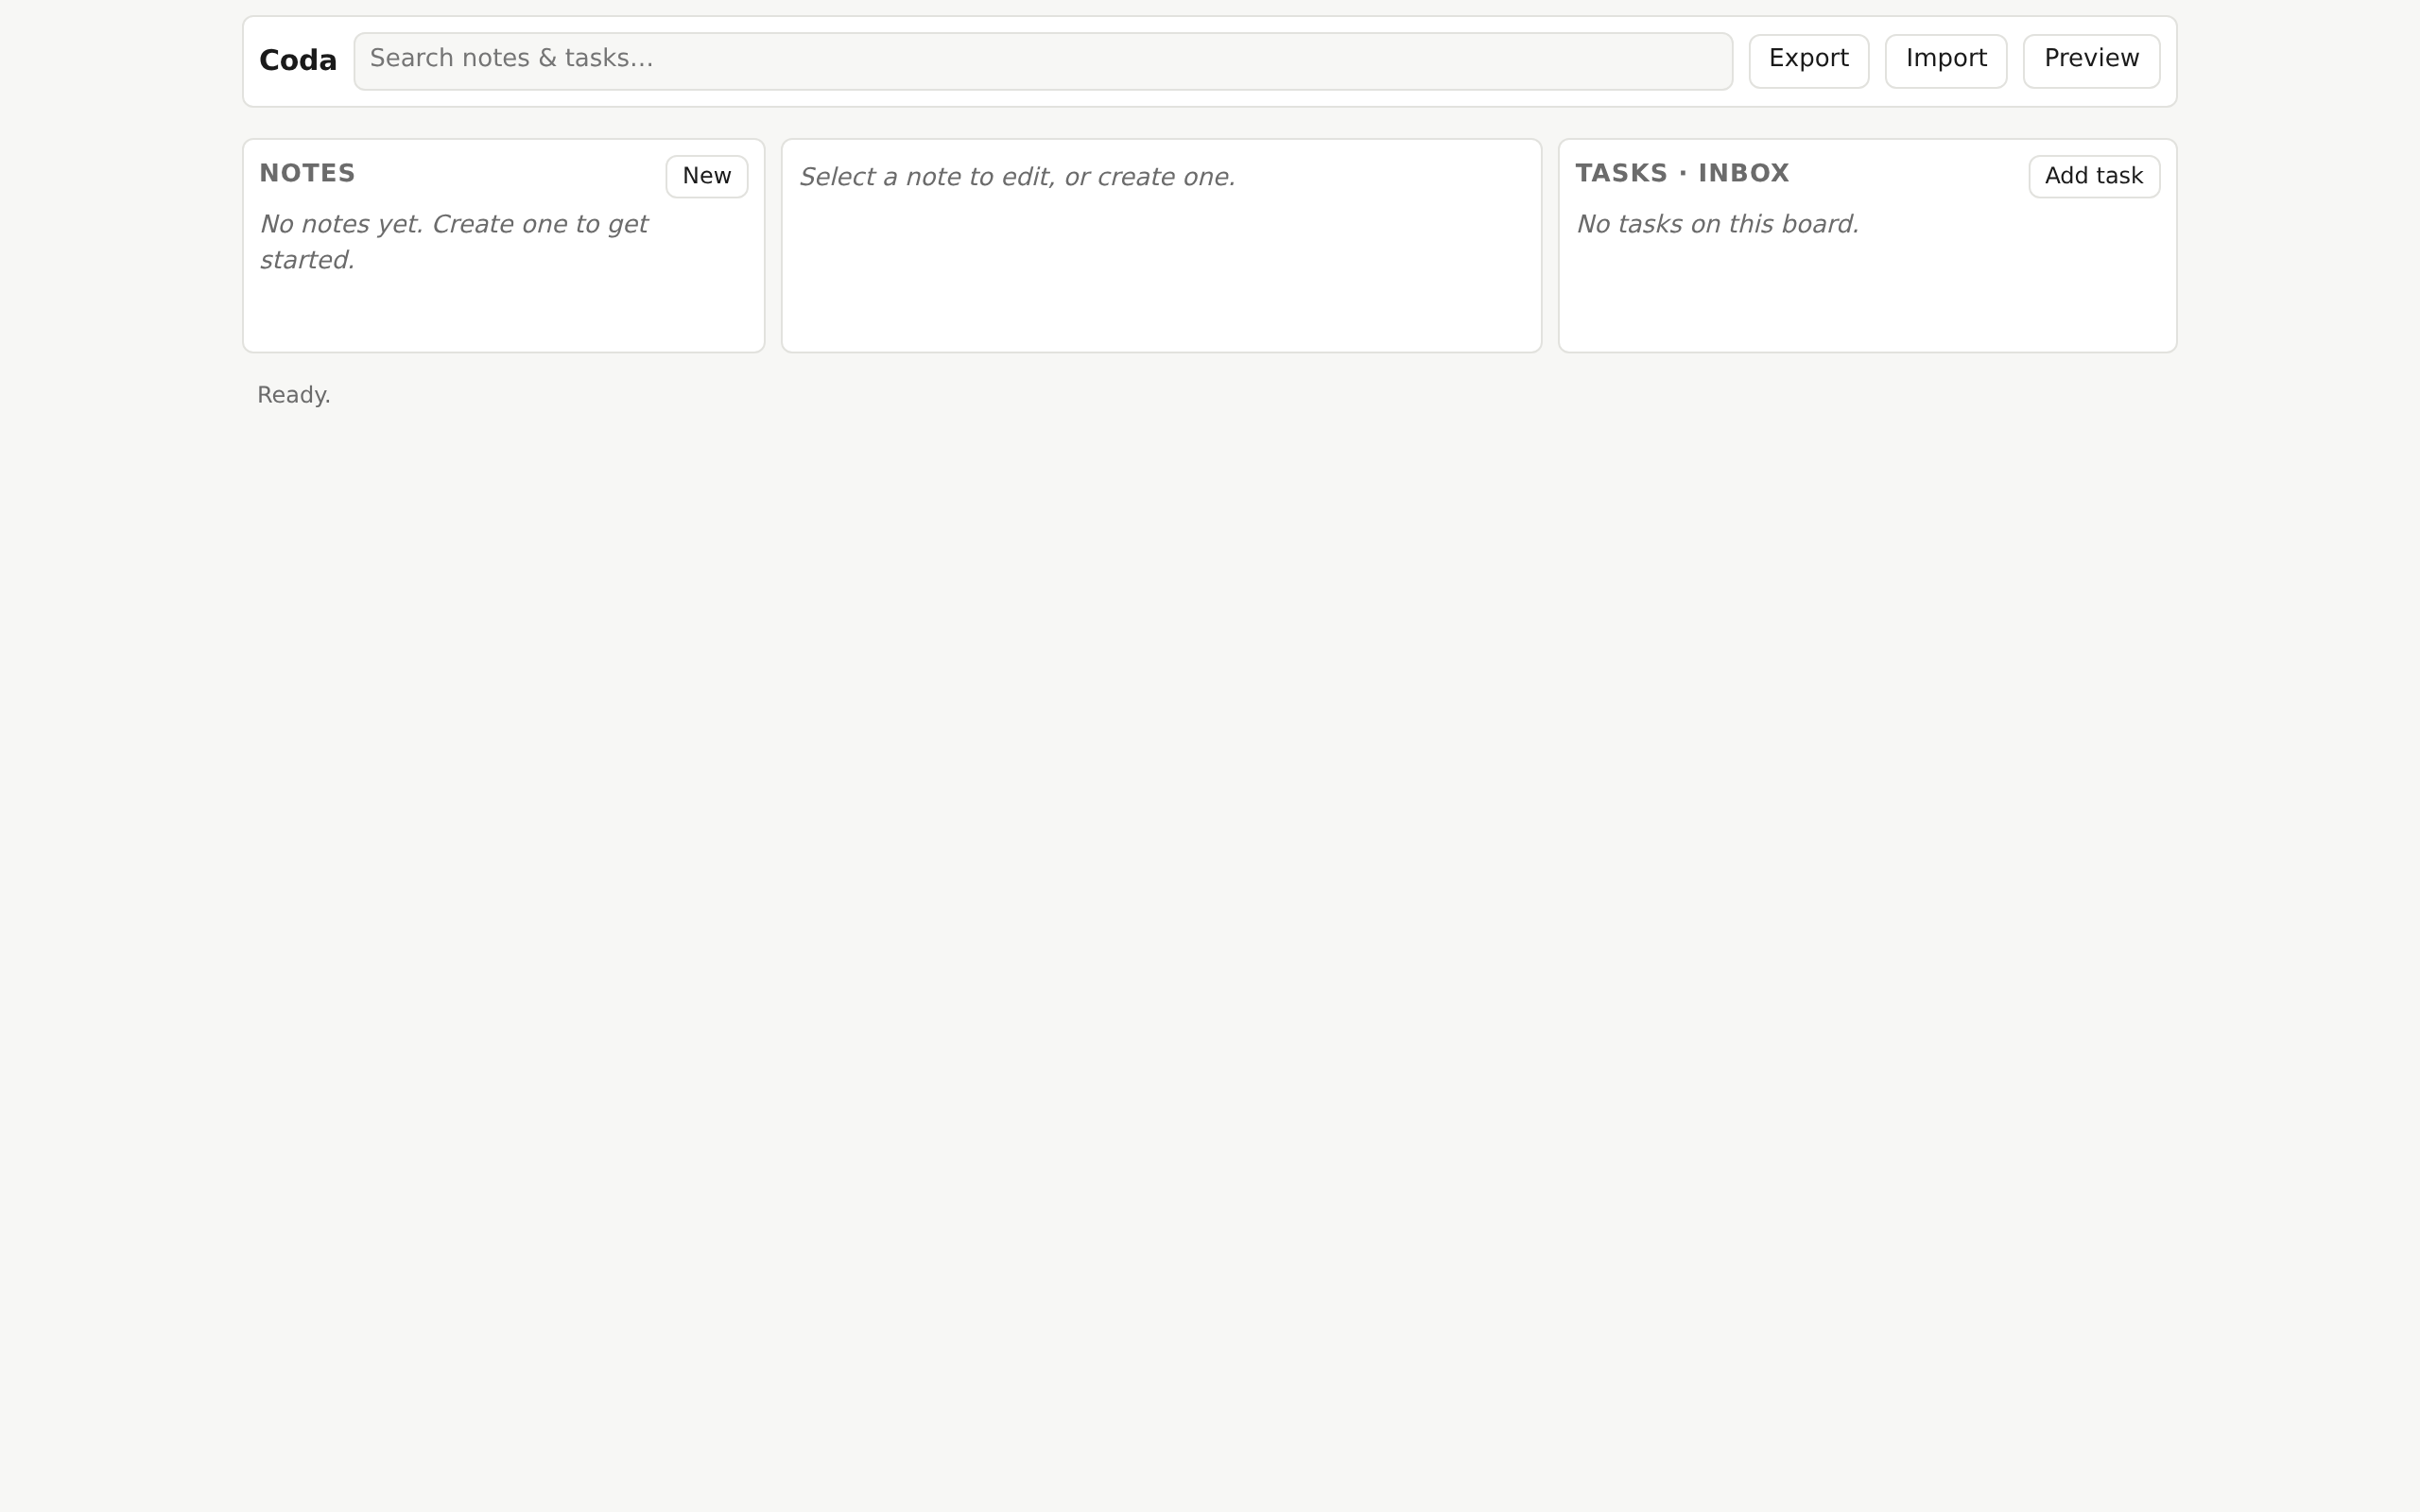
coda — Fresh boot — the app at "Ready."
Coda — the app at its real ready marker on a fresh context: the seeded notes list and task board, no user data
Fresh boot — the app at "Ready."
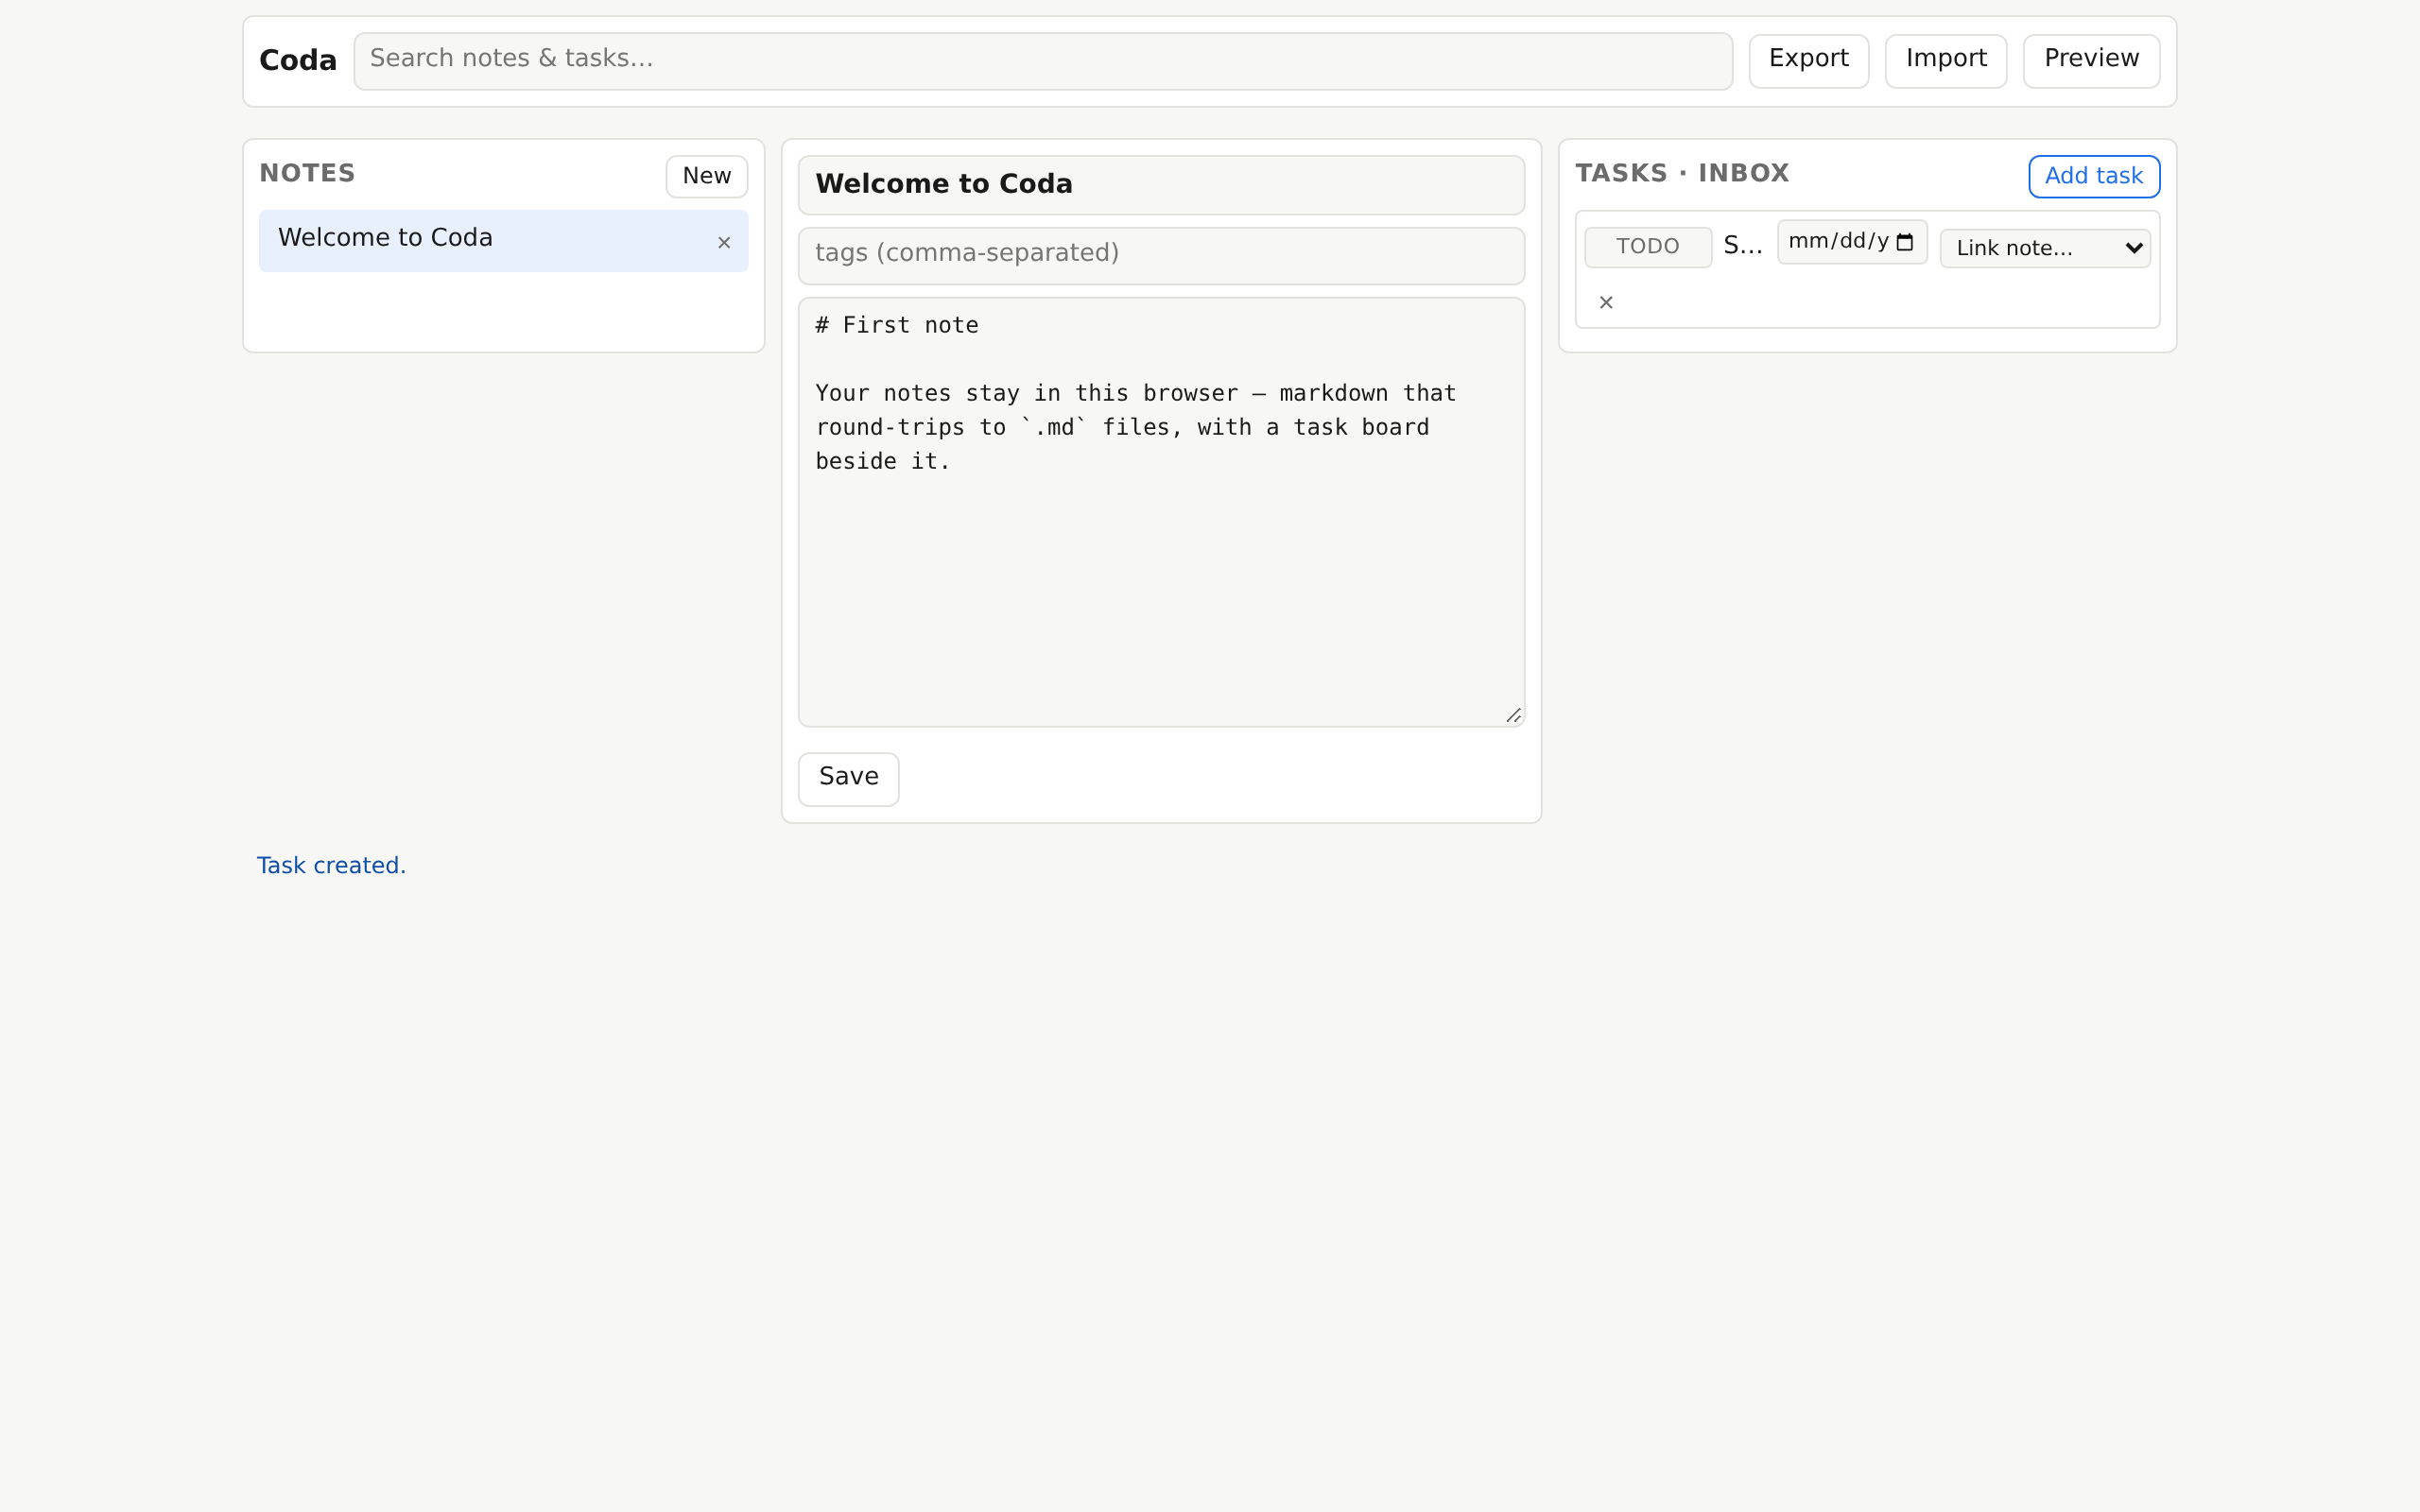
coda — In use — the e2e spec's own interactions, the real DOM
Coda in use — the same app after the e2e spec's own interactions: a saved note and a task created through the real UI
In use — the e2e spec's own interactions, the real DOM

the docsthe PWA benchmark lane

The second user product

Ostinato — the repo's second app that left the terminal

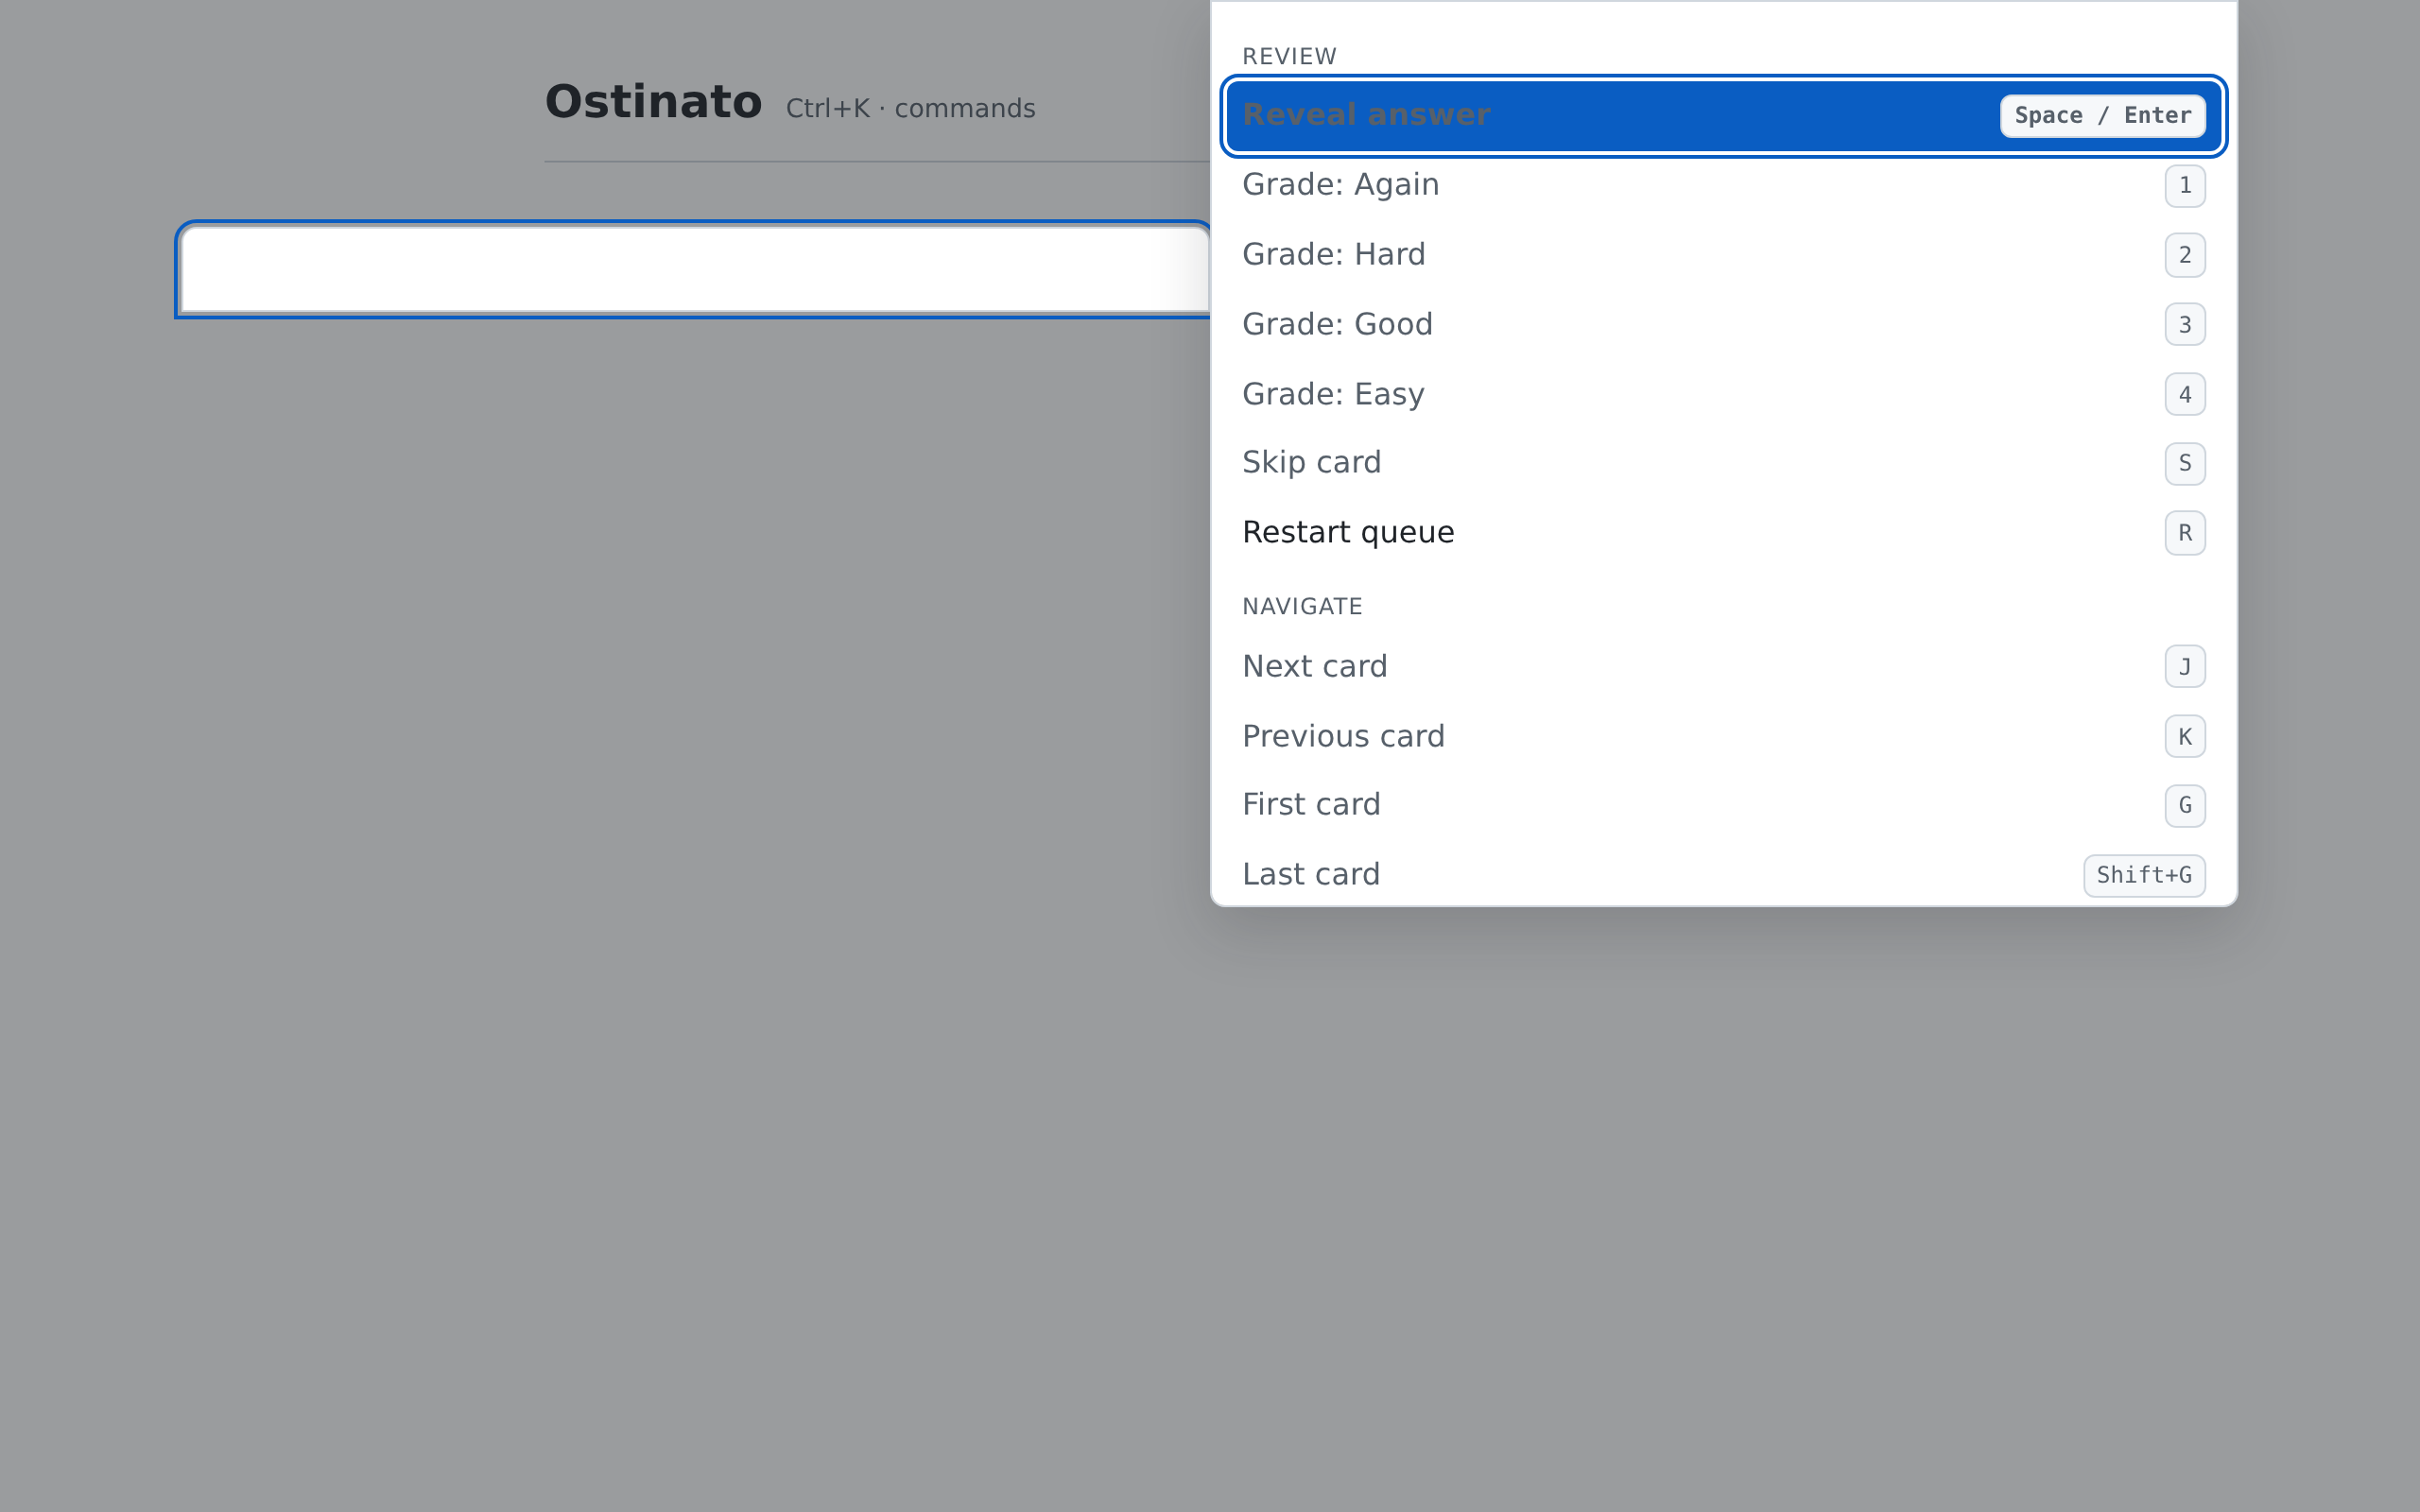
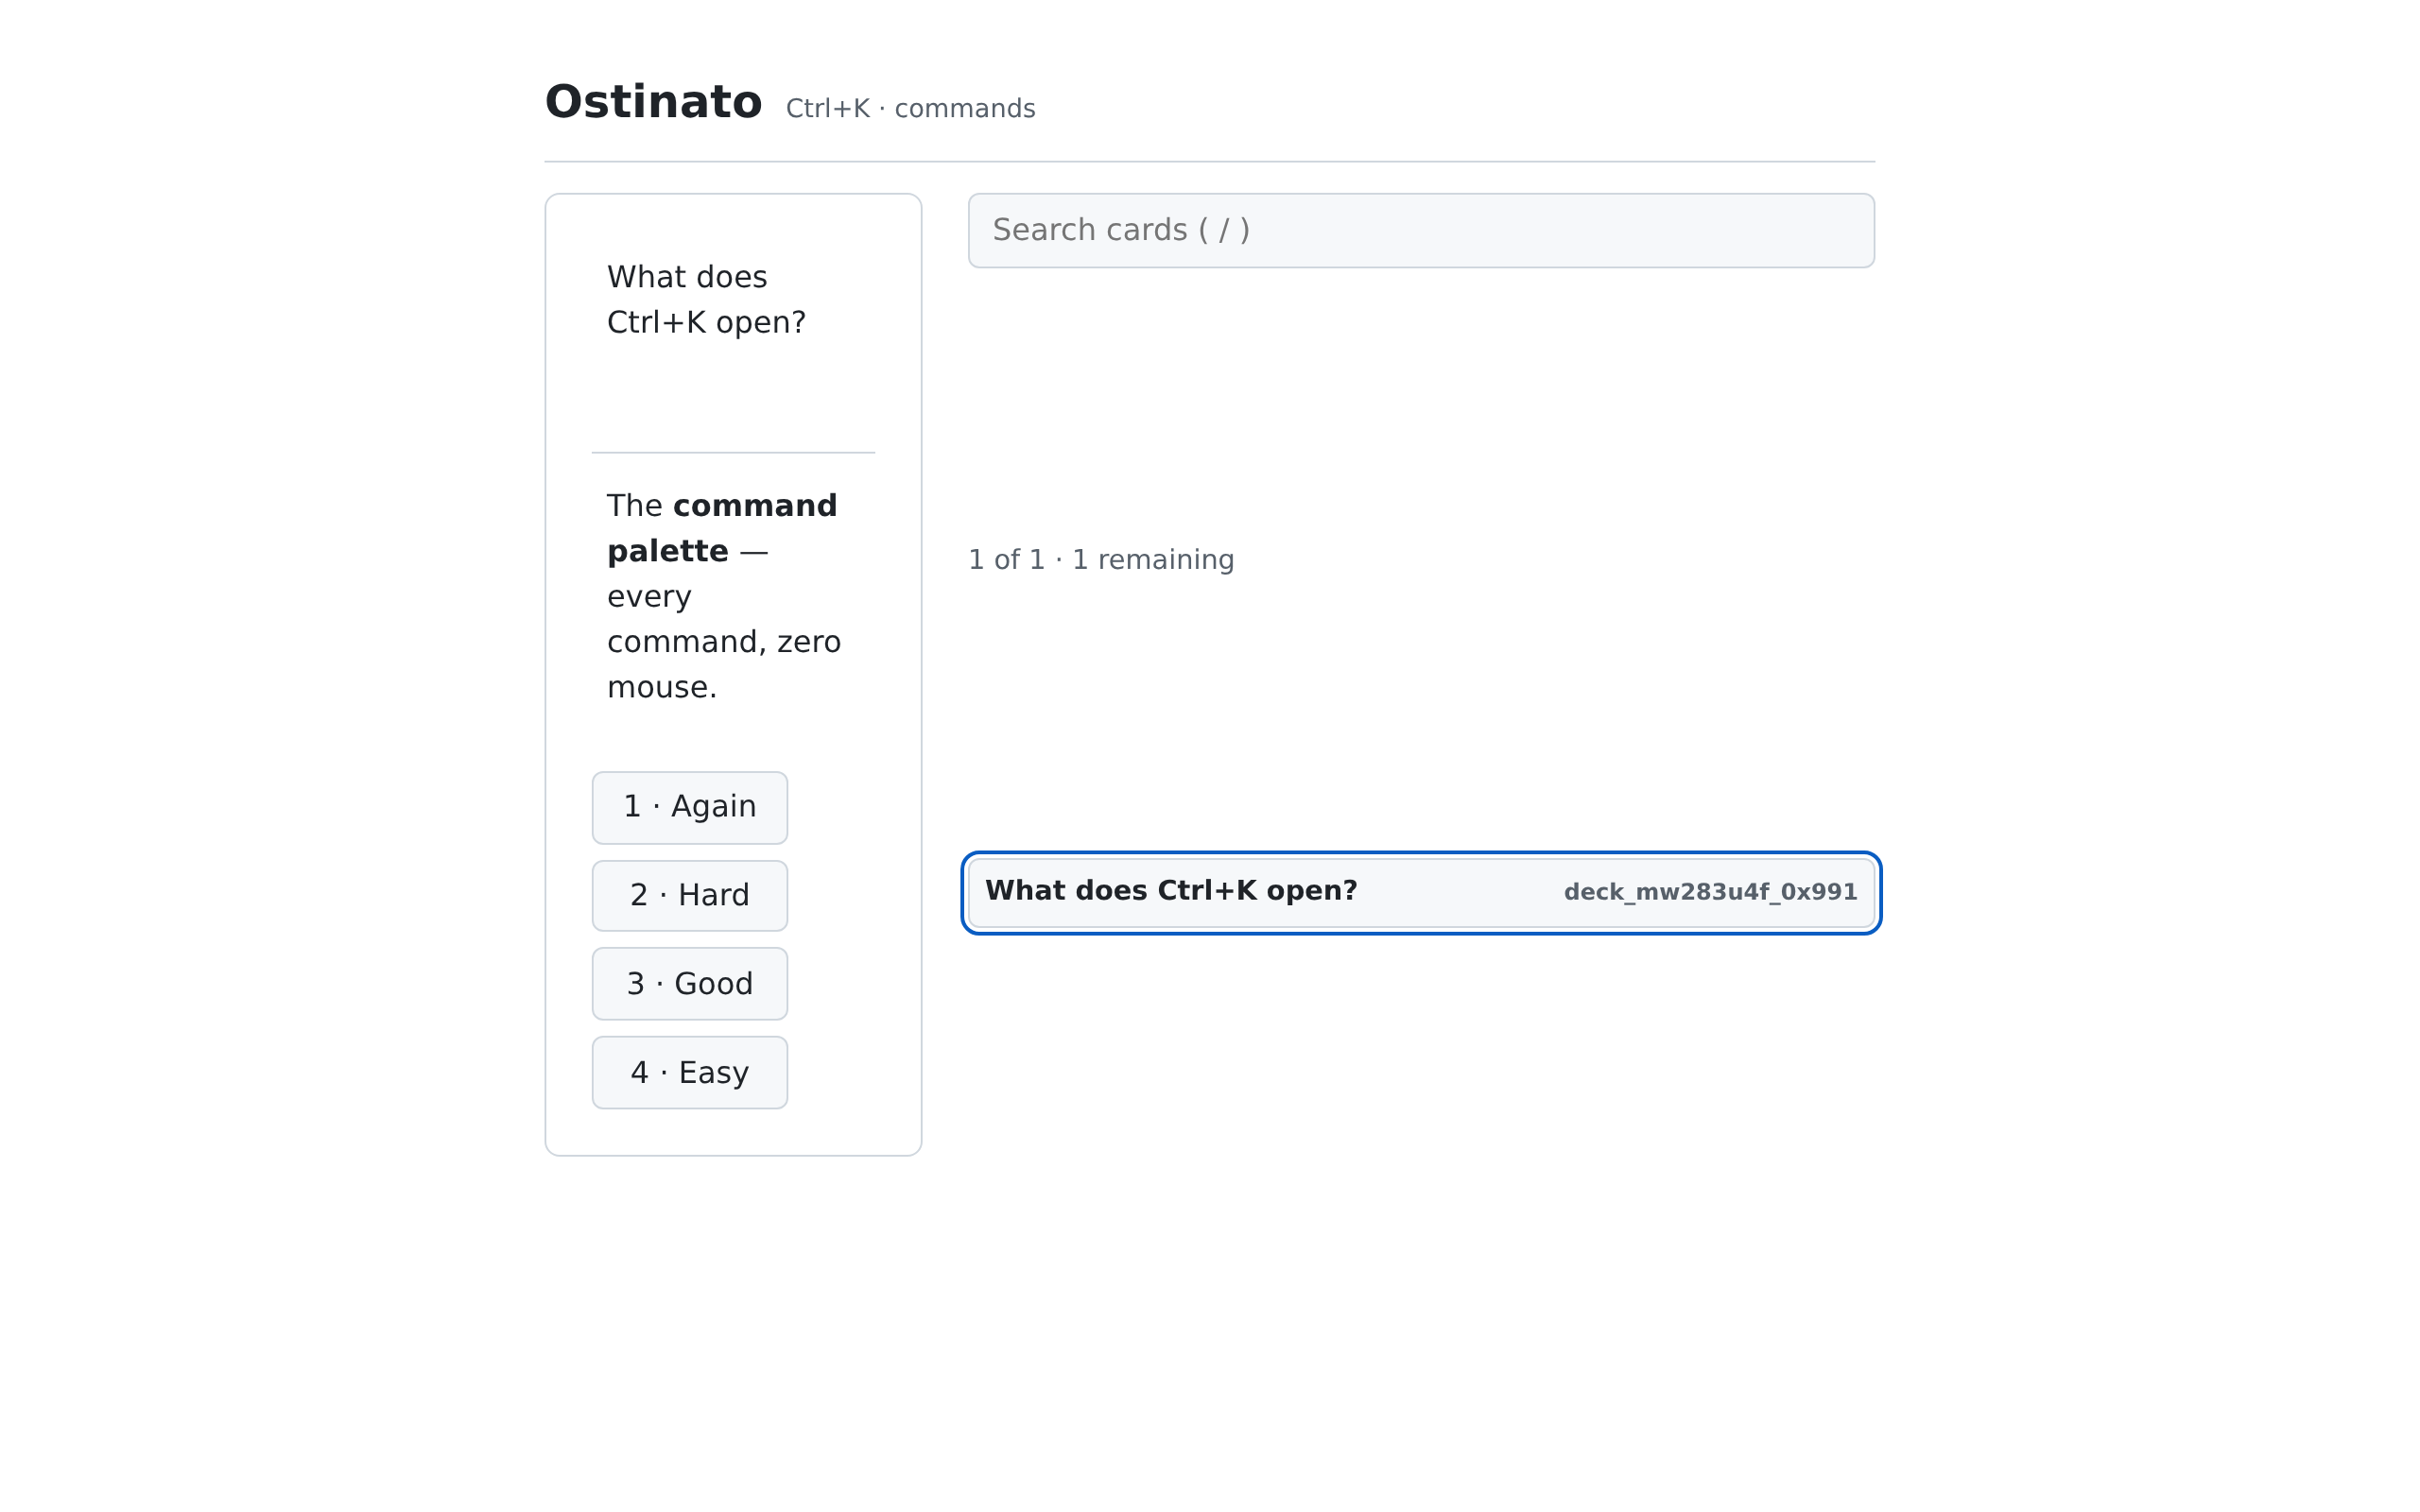
The repo's second user-facing app: a keyboard-first, offline-first spaced-repetition flashcard PWA. SM-2 scheduling, markdown decks, JSON import/export, crash-safe mid-review resume. Honest scope: Chromium-desktop-only.

ostinato — The command palette — keyboard-first
Ostinato with the command palette open — every workflow reachable by keyboard
The command palette — keyboard-first
ostinato — The reveal — markdown on the back face
The card's back face revealed, with markdown rendered
The reveal — markdown on the back face

the hardening battery: 12 specs across five lanes — 12/12, keyboard-only, axe-clean both schemes, offline, crash-resume — 8.5 s first run / 7.2 s re-run (headless chromium, the external Playwright verifier)

the docsthe benchmark lane

The third user product

Chaconne — the repo's third app that left the terminal

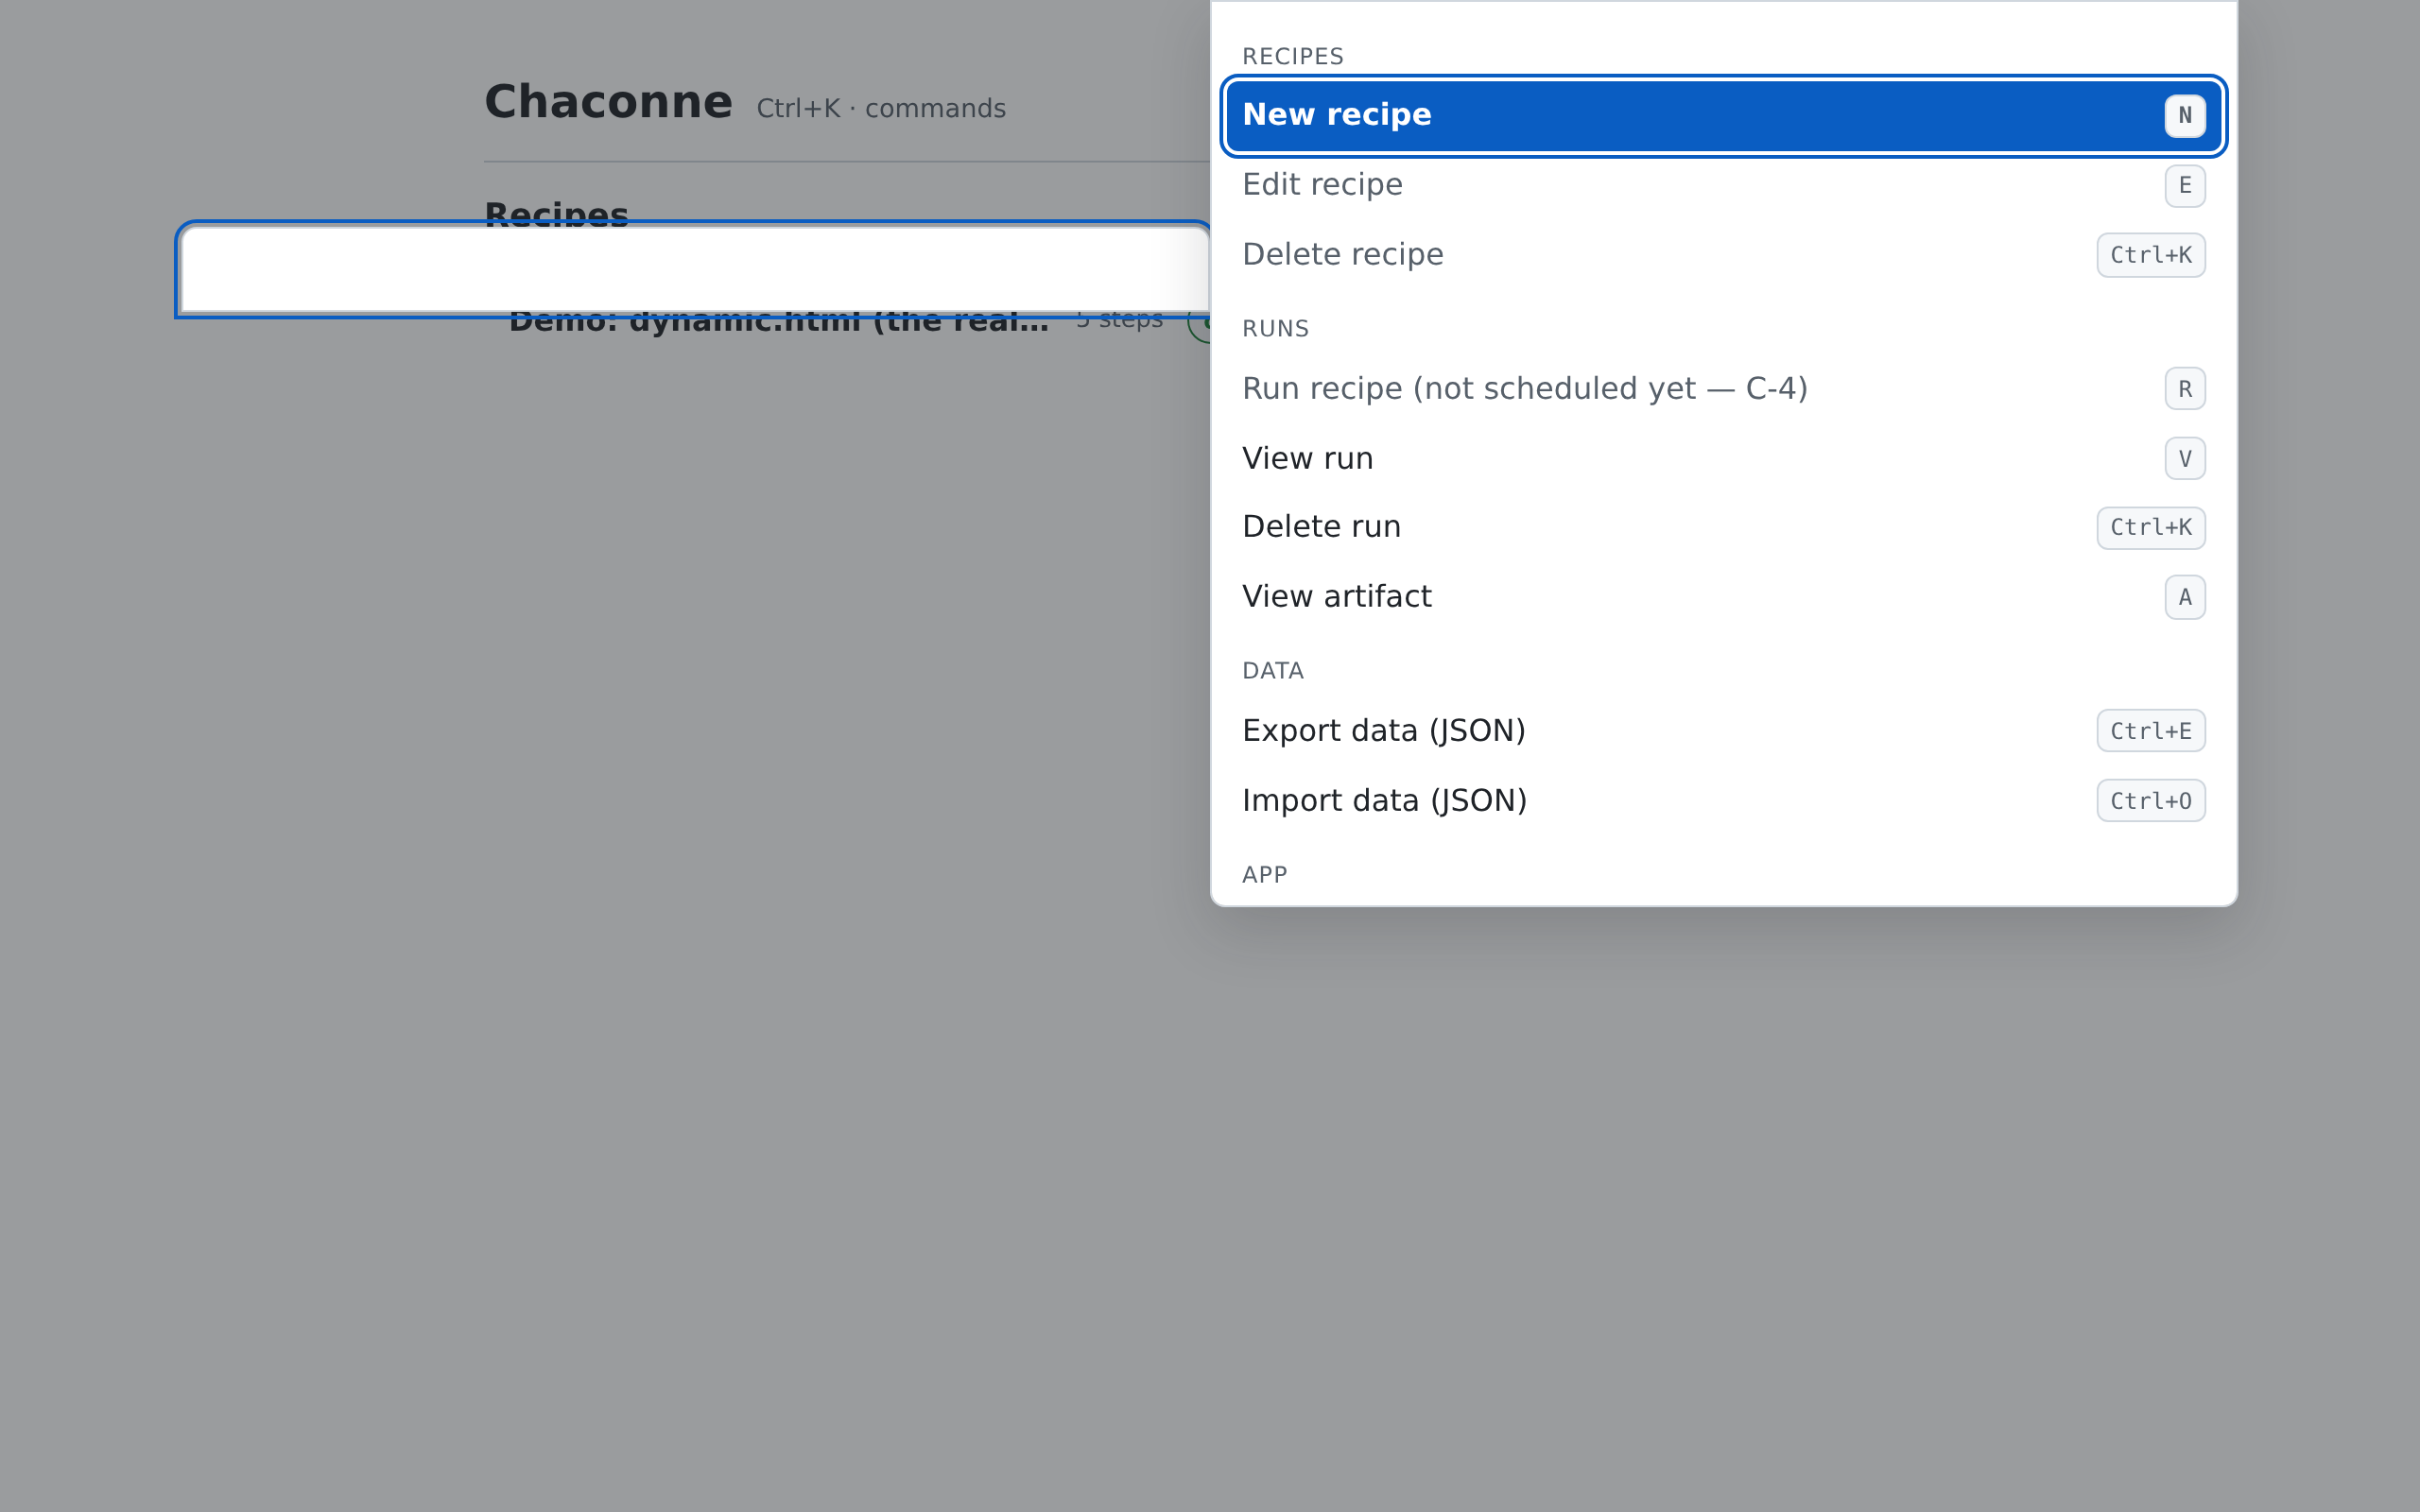
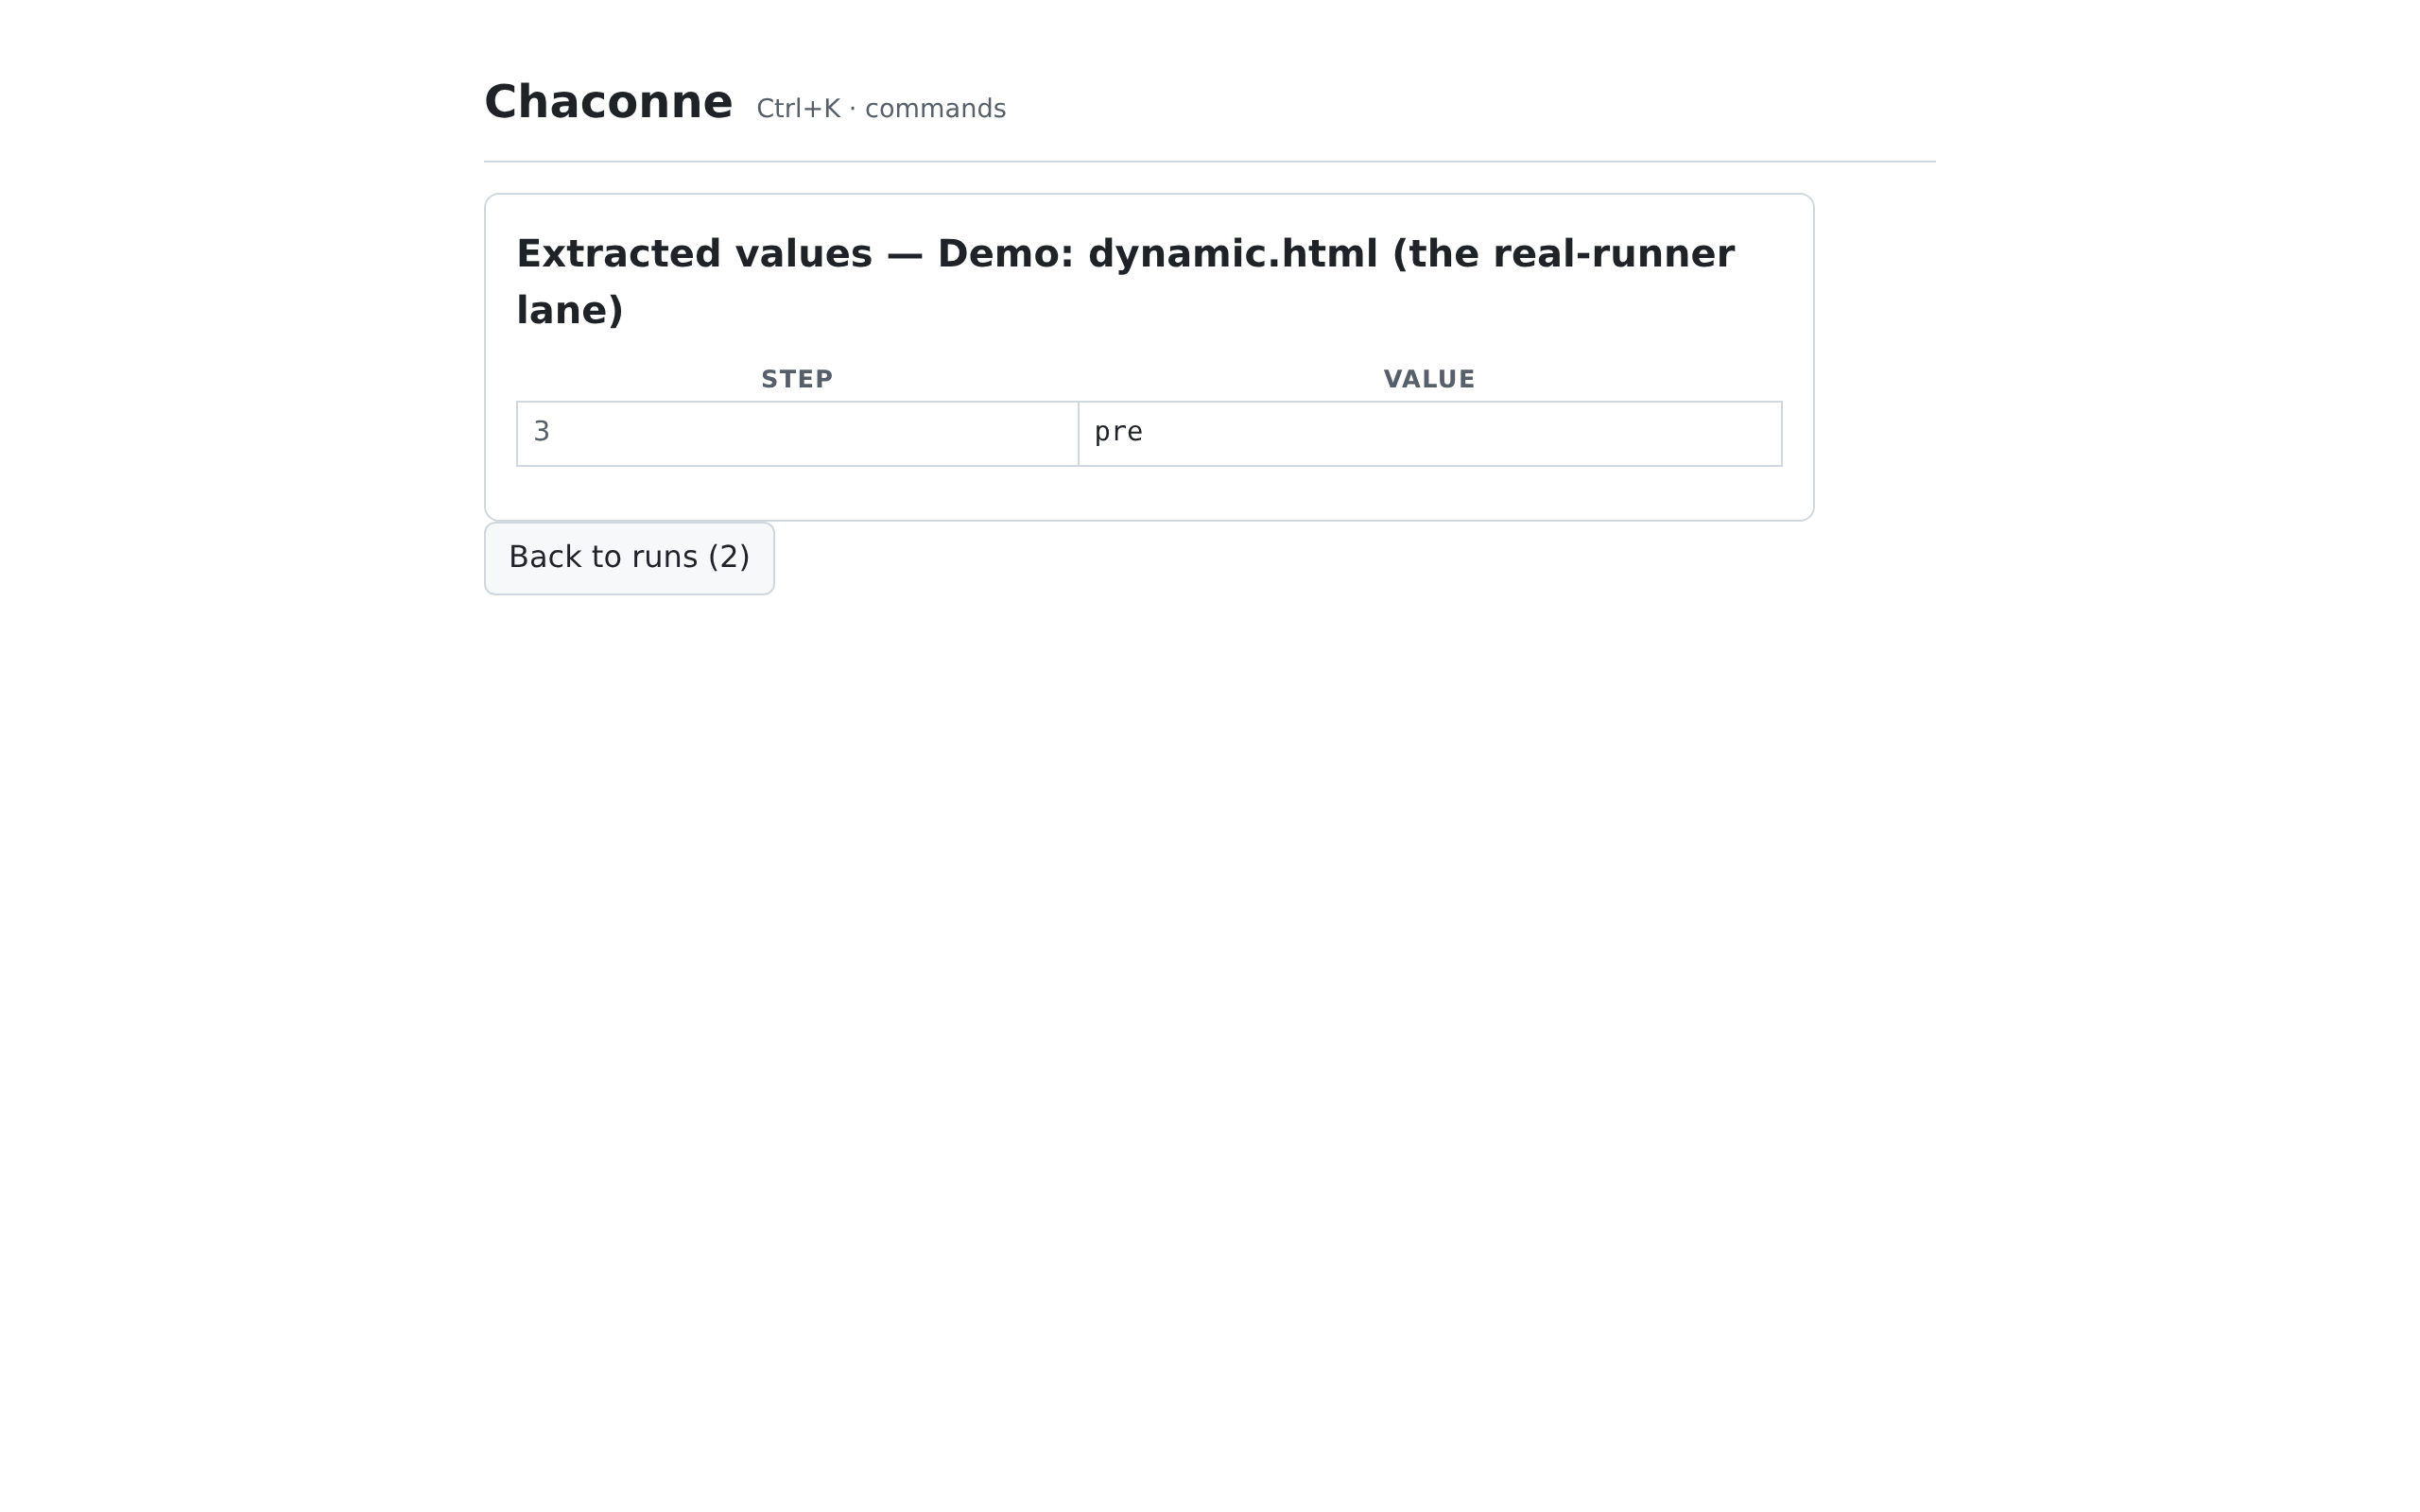
The repo's third user-facing app: a keyboard-first, self-hosted browser-recipe runner PWA. Compose a flow — goto, click, fill, assert, extract, screenshot — and it repeats on a schedule, capturing a content-addressed artifact and an honest run record every time. Fixture-verified by construction: every test lane runs against local fixture pages, never the live network. Honest scope: Chromium-desktop-only.

chaconne — The command palette — every action, one keystroke apart
Chaconne with the command palette open — every recipe, run and data command enumerated with keyboard hints
The command palette — every action, one keystroke apart
chaconne — The artifact viewer — the run's evidence, content-addressed
The artifact viewer: a run's screenshot panel and extracted-values table
The artifact viewer — the run's evidence, content-addressed

the docsthe PRD

The fourth user product

Fugue — the repo's fourth app that left the terminal

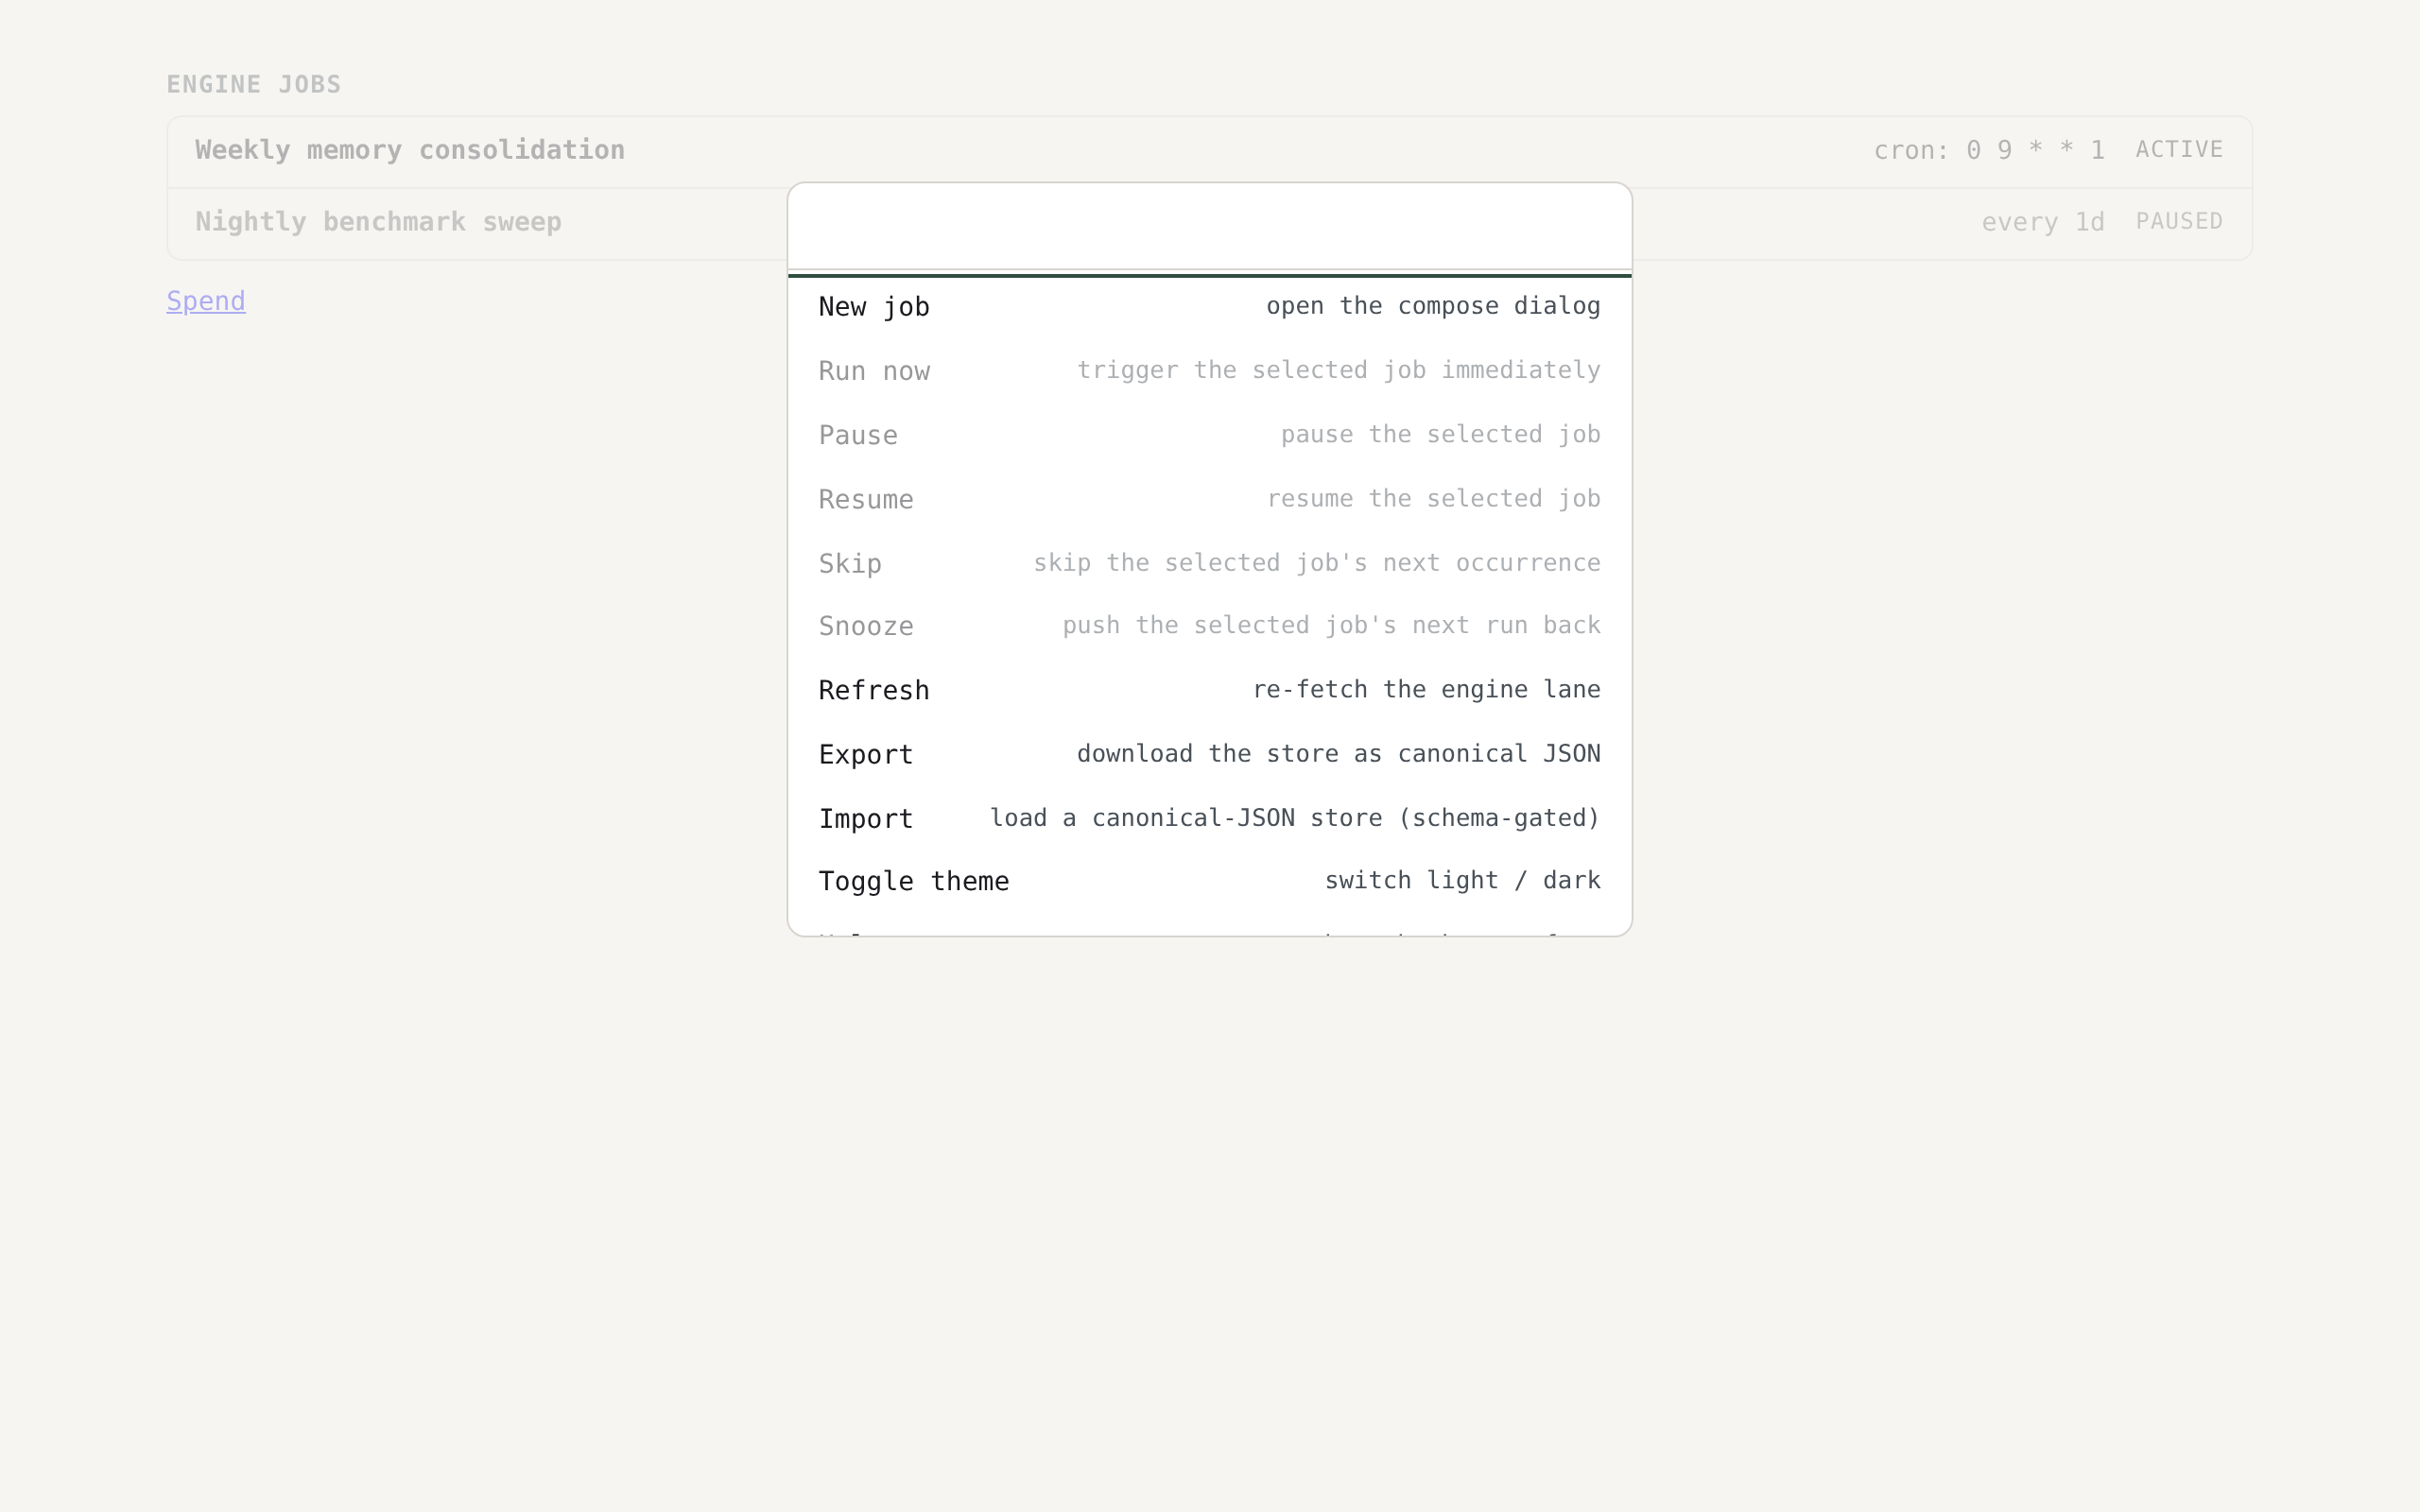
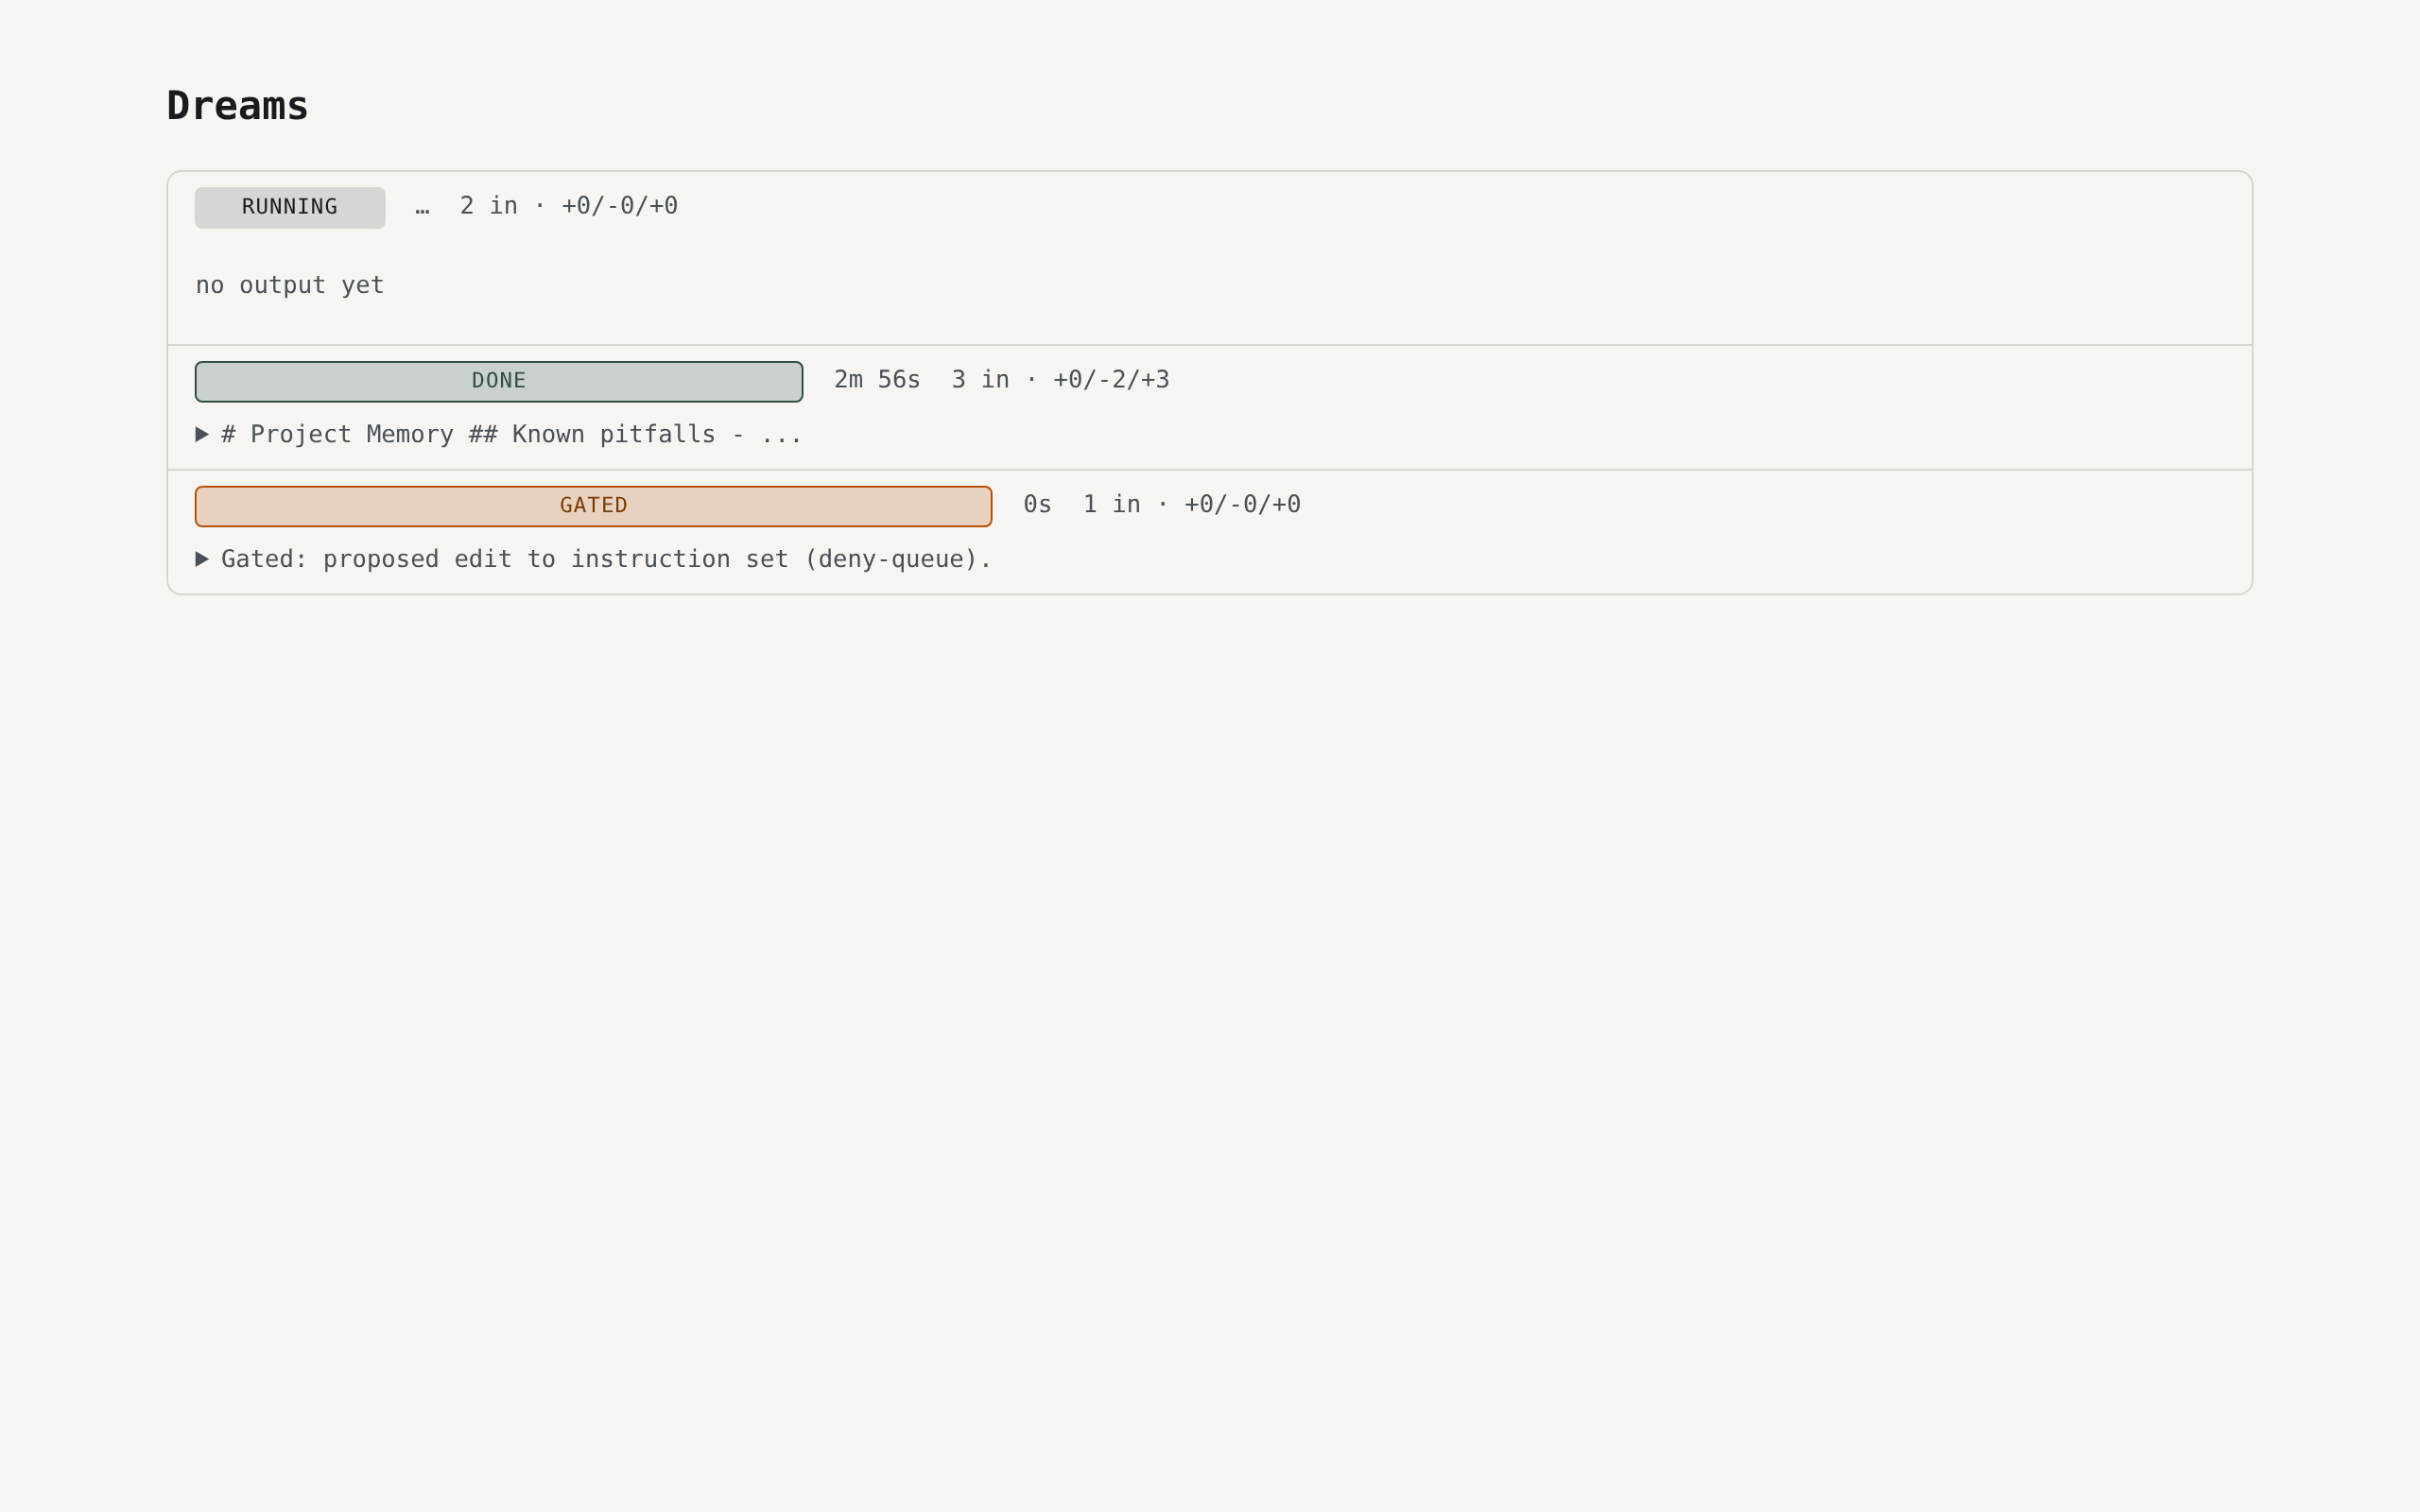
The repo's fourth user-facing app: a keyboard-first PWA console for the engine's own automation + learning loop — author, pause, resume, skip, snooze and run-now the scheduled agent jobs, watch runs back with honest status and tokens, curate the AutoDream journal, the memory tiers and the staged-skills queue. Fixture-verified: every test lane runs canned contract-pinned JSON, never the live network. Honest scope: Chromium-desktop only.

fugue — The command palette — every action, one keystroke apart
Fugue with the command palette open — every job, run and learning command enumerated with keyboard hints
The command palette — every action, one keystroke apart
fugue — The dreams journal — the learning loop, as the product surface
The dreams journal: the AutoDream consolidation log with the five-status badge vocabulary and the expandable output preview
The dreams journal — the learning loop, as the product surface

the docsthe round receipts

The fifth user product

Legato — the repo's fifth app that left the terminal

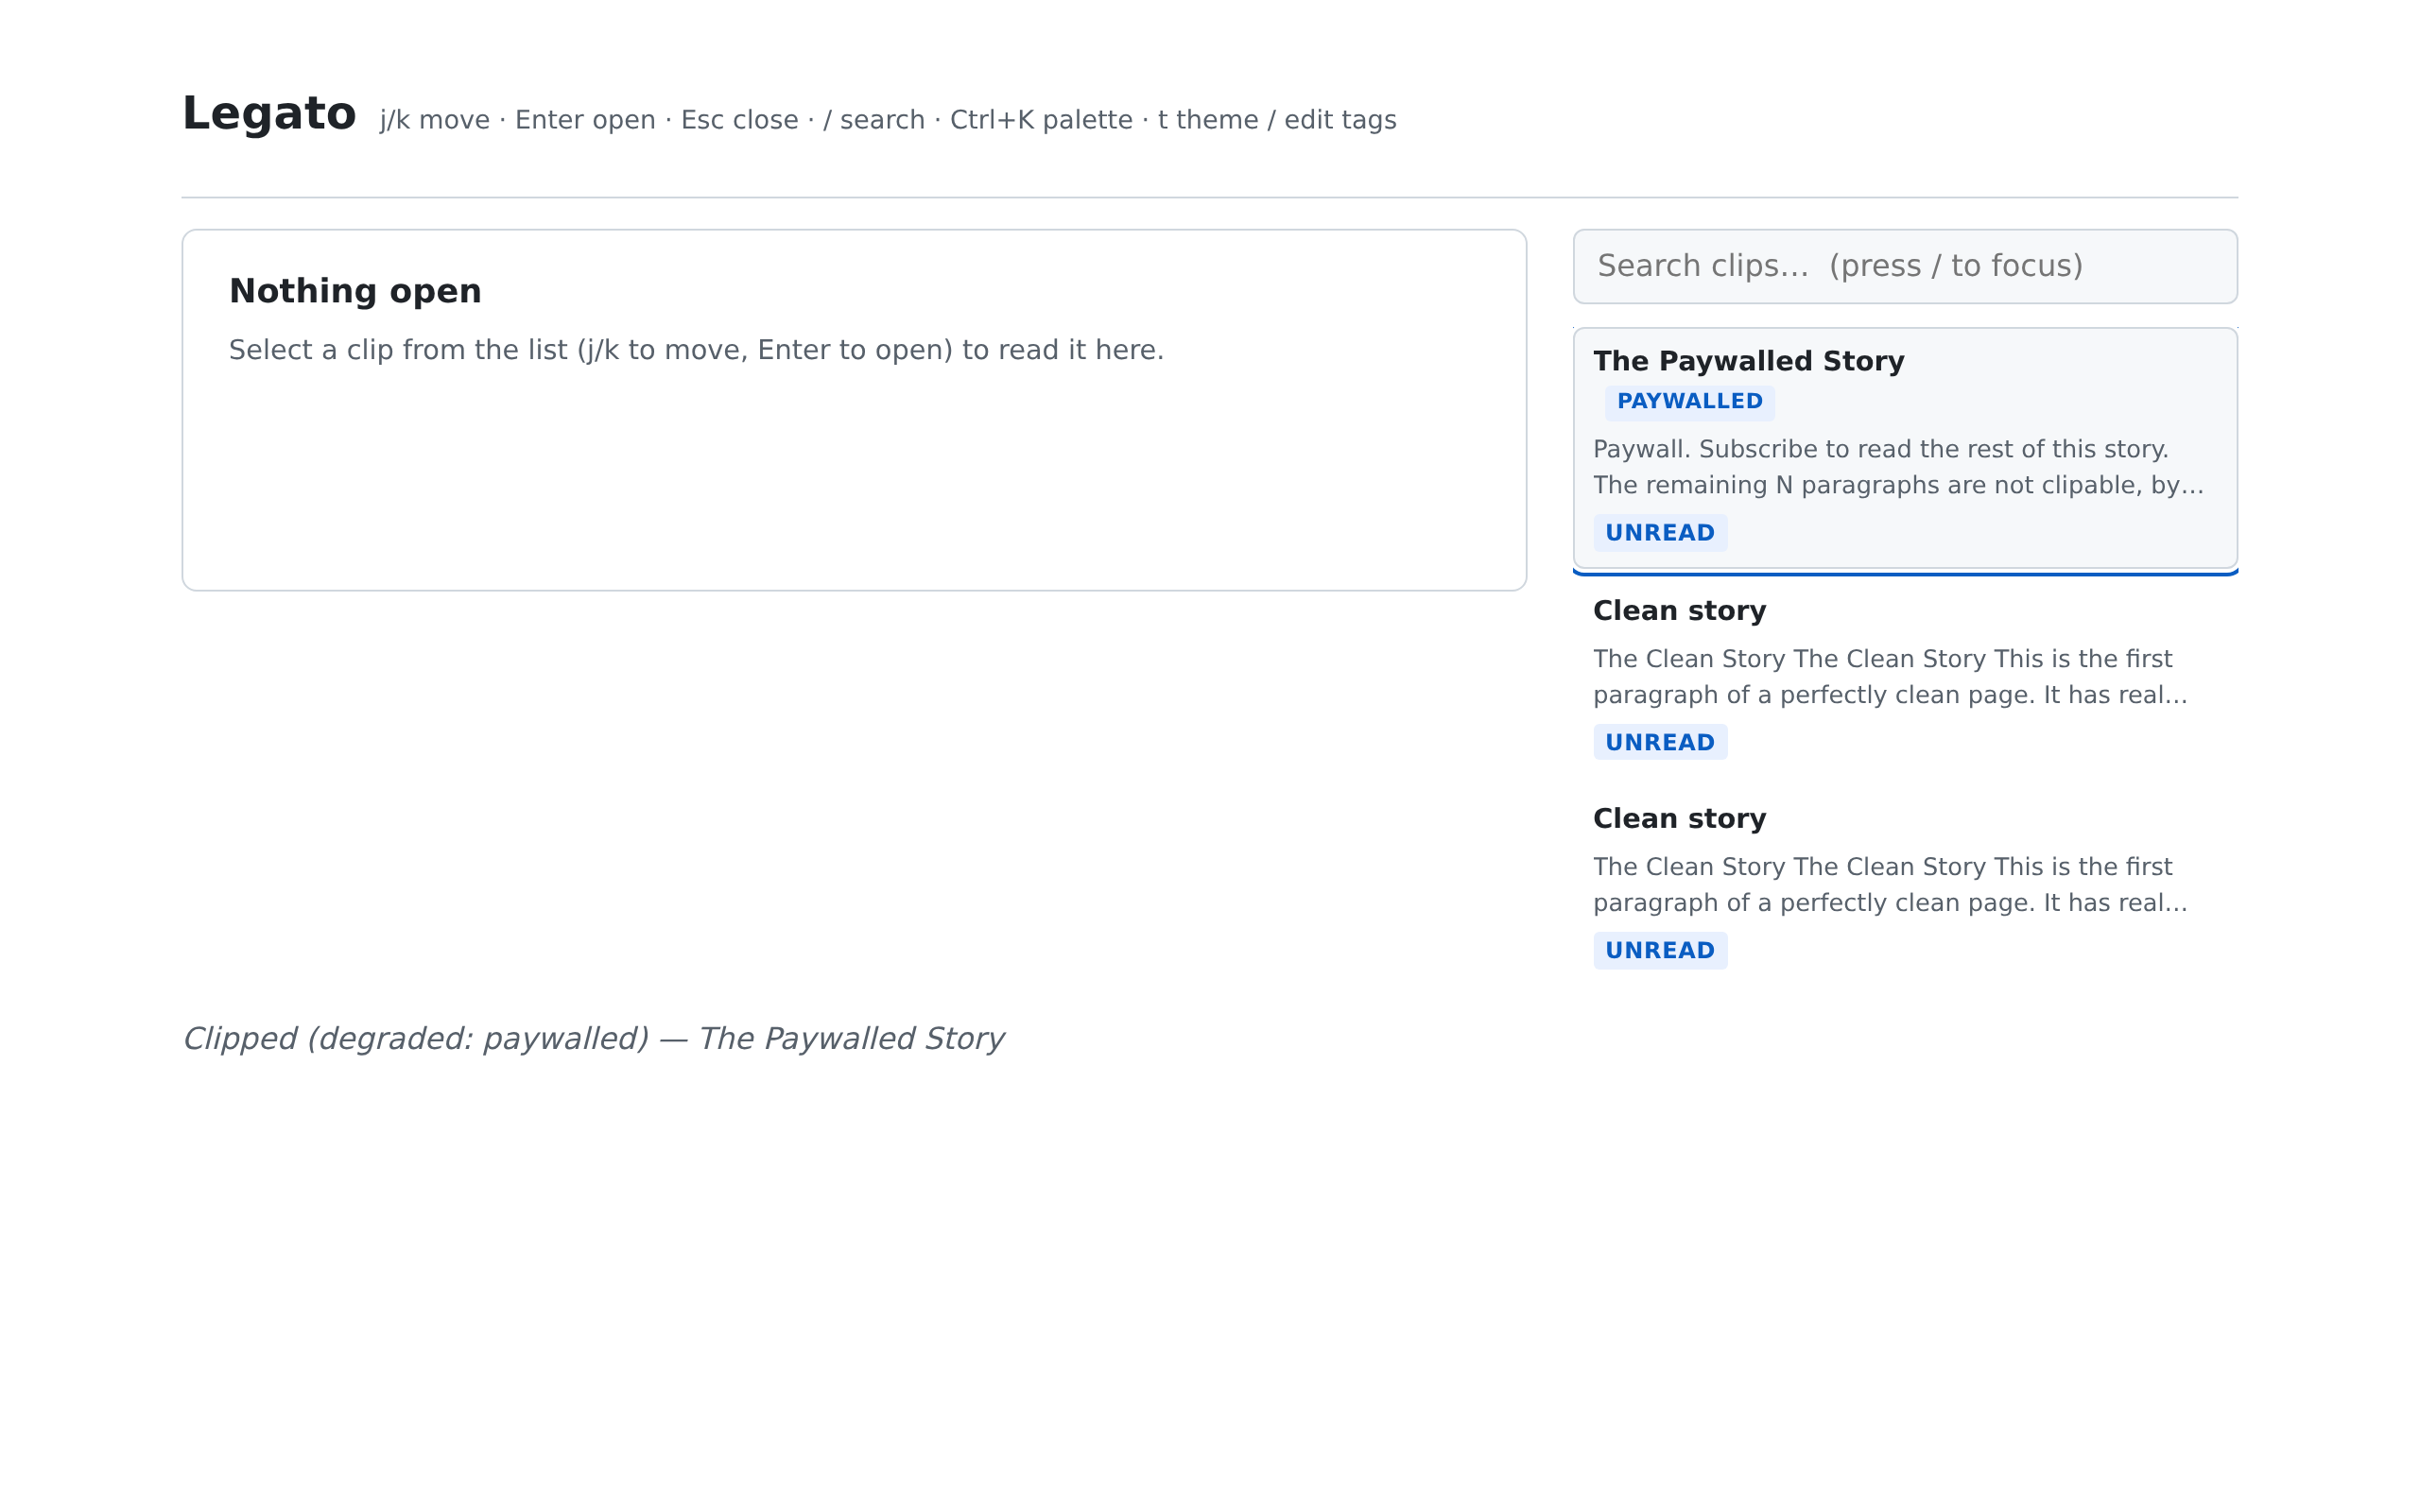
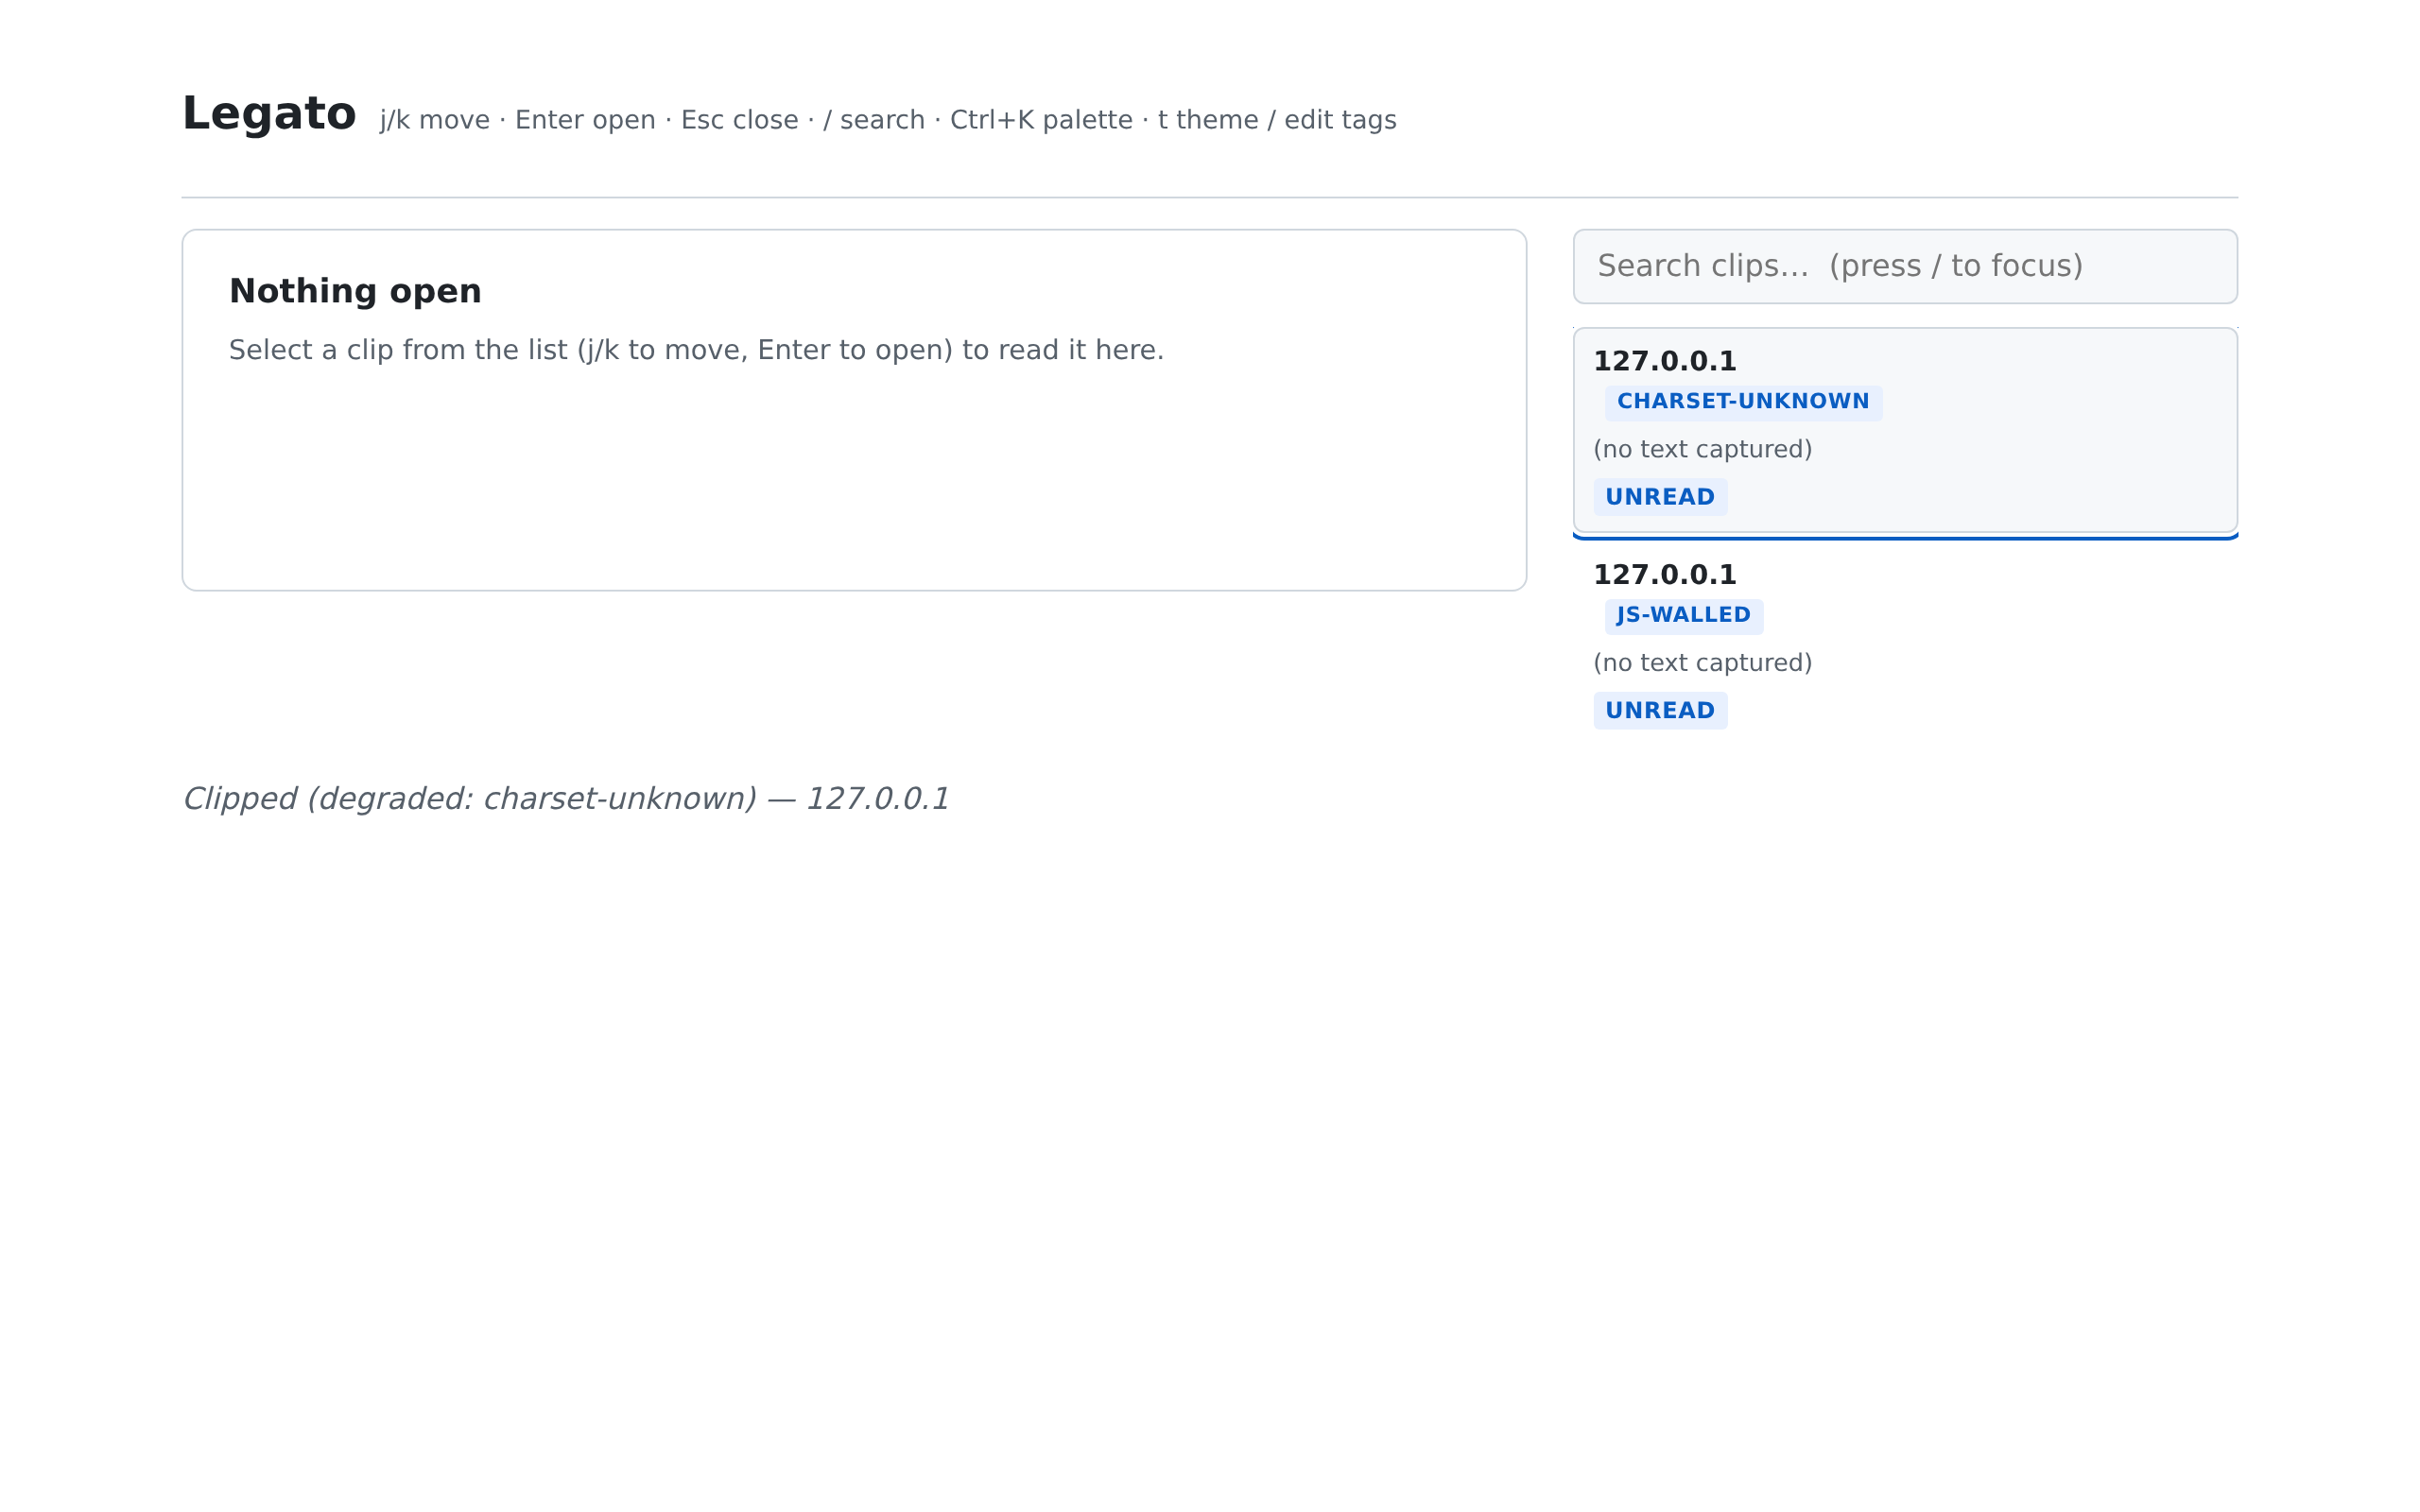
The repo's fifth user-facing app: a keyboard-first, offline-first read-later PWA — clip any URL, get a clean readable copy stored locally, find it again with full-text search + tags, read in a keyboard-driven queue, highlight what mattered, carry everything in a byte-stable JSON bundle. Fixture-verified: every test lane runs against the hostile fixture server, never the live network; the js-walled fallback is an honest title+URL+flag, never a bypass. Honest scope: Chromium-desktop only.

legato — The reading inbox — real clips, clipped through the app's own keyboard flow
Legato's clip list with real clips seeded through the app's own keyboard clip flow — the clean story, the redirect chain, and the paywall excerpt, each row with its extracted title and state badge
The reading inbox — real clips, clipped through the app's own keyboard flow
legato — The hostile-clip honesty — every taxonomy lane degrades, never silently
Legato's hostile-clip outcomes — two degraded rows from the app's own clip flow against a walled and a wrong-charset fixture, each with its honest taxonomy badge
The hostile-clip honesty — every taxonomy lane degrades, never silently

the docsthe round receipts

Proof

Receipts, not promises.

Every number is generated from receipts and re-checked in CI — including where memory made things worse.

52%

LiveCodeBench v6 pass@1

post-cutoff problems, kimi-k2.5

98.1%

edit accuracy

106-fixture oh-my-pi benchmark

−35%

warm wall time

repeat tasks, kimi-k2.5

0/50

attacker rules shipped

MPBench-adapted corpus, 0 planted

LiveCodeBench v6 — the contamination-aware headline

50-problem stratified subset of LiveCodeBench's release_v6 increment · contests 2025-01-04 → 2025-04-06 · after every model's cutoff · official LCB prompt + grader · greedy pass@1 · four models: the Dashscope trio (2026-10-17) + agnes-3.0-flash on Agnes AI (2026-10-21)

kimi-k2.552.0
qwen3.7-plus38.0
qwen3.6-plus36.0
agnes-3.0-flash28.0

Every problem postdates these models' training cutoffs. Easy sweeps for three of four (13/13, 12/13, 12/13); hard is where it ends (4/23, 1/23, 1/23, 0/23). no_code is the honest failure mode: reasoning past the pinned 4096-token budget gets cut off before the code fence closes — 15/26/27/35 of 50, reported as measured, not filtered.

benchmarks/livecodebench/results/

Edit accuracy

oh-my-pi typescript-edit-benchmark · 106 fixtures · byte-exact scoring · full Unown agent in the loop · Dashscope trio: 2026-10-17 fresh-checkout rerun · agnes-3.0-flash: 2026-10-21 Agnes AI rerun (97.2% at n=1, in the trio's band)

kimi-k2.598.1
qwen3.7-plus96.2
qwen3.6-plus94.3
agnes-3.0-flash97.2

head-to-head against the oh-my-pi agent, same 106 fixtures, 3 runs per task: identical best-of-3 scores on every model — and 2.4–5.4× fewer input tokens.

Memory lift, cold vs warm

n=10 · single run per phasebenchmarks/selfimprove/results/

Each model solved the same 10-task Python Exercism set cold (fresh project, fresh memory), then warm: a new workspace carrying only the memory dreamed from its cold pass. Bars are input tokens, normalized per model; the scale runs to 300% — recomputed from these receipts, so the models that spent more widen the axis, never cropped.

coldwarm · fewer input tokenswarm · more input tokens
qwen3.6-plus−23.7% in25s → 23s −8.0%pass 10/10 → 10/10
401,445 → 306,218
kimi-k2.5+21.8% in37s → 24s −35.1%pass 10/10 → 10/10
34,553 → 42,075
qwen3.7-plus+23.2% in24s → 25s +4.2%pass 10/10 → 10/10
64,853 → 79,886
agnes-3.0-flash+197.1% in106s → 79s −25.5%pass 9/10 → 9/10
107,583 → 319,659

Pass-rate lift is 0pp across all four models: three of four spent more input tokens with memory — agnes-3.0-flash most of all (+197%, dreamed user-tier memory injected into every warm session) while finishing 26% faster — and kimi-k2.5 finished 35% faster; qwen3.6-plus took both wins. On tasks the model can already solve, memory buys efficiency, not correctness.

Negative controls, published as-is

v1 (thin session notes only): −25.6% input, 64s → 34s warm, with an unchanged memory file — that saving is upstream prompt caching, not memory; v1 stays as the control arm isolating the confound. v3 (six sequential sessions, one evolving repo, real dreams): 6/6 with memory, 6/6 without, 6/6 with wrong-domain memory — learned memory cost +36% billed input tokens, irrelevant memory +30% and bought nothing. The memory system now has a live suite — injection proven by a unique marker in the captured upstream request, real dream + canary + rollback roundtrips, a ten-variant poisoning corpus: every adversarial note flagged at the input layer, 0/10 attacker rules planted into dreamed memory, 0 shipped — receipts in benchmarks/memory-eval/results/.

HumanEval+

official evalplus CLI · 164 problems · greedy pass@1 · 2026-10-21 rerun (per-model runs)

kimi-k2.593.9
qwen3.6-plus93.3
qwen3.7-plus92.7
agnes-3.0-flash89.0

predates these models, so it cannot separate ability from memorization — exactly why LiveCodeBench above is the headline.

Aider polyglot subset

50 exercises · 6 languages · Aider's 2-attempt protocol · pass@2

qwen3.6-plus96 @96
qwen3.7-plus96 @96
kimi-k2.594 @94
agnes-3.0-flash96 @90

first published polyglot numbers for the Dashscope trio (2026-10-17 rerun reproduces the committed run) · agnes-3.0-flash from the 2026-10-21 Agnes AI campaign: 90% @1 / 96% @2

Long-horizon refactor

one hard multi-file contract change, 11-module TypeScript app · n=1 · scored on the diff

kimi-k2.543.5k in
qwen3.7-plus62.6k in
qwen3.6-plus1205k in
agnes-3.0-flash62.0k in

all four solved it — agnes-3.0-flash left the greenest as-is suite (42/0); the separation is cost: qwen3.6-plus spent 1.2M input tokens with zero cache reads (28× kimi), while agnes-3.0-flash rode 1.07M of cache reads, the strongest prompt-reuse profile measured. receipts

The regression layer below the loop

three suites · every push

A self-improving agent regresses its own harness first: a bad memory ship looks like a better model. The loop sits on a locked suite that stays green while everything above it evolves — anti-tamper scoring (tests restored before scoring), pinned datasets and harness versions, official harnesses only, per-task JSONL receipts under benchmarks/.

dashboardsrc/**/__tests__/*.test.tsxbun run test:unit
llm-bridgemini-services/llm-bridge/pure.test.tsbun test pure.test.ts
enginepi-repo/packages/self-learning/testbun test test/

not measured here — SWE-bench Verified and Terminal-Bench 2.0 are quoted from vendor reports, never our own runs. The one eval that scores zero (our extension-authoring eval, 0.0 for every model) sits in Integrity.

The alphabet

The name is a pun you have to read twice.

unown — the Symbol Pokémon: a flat black letter with one eye, alive since 1999. Twenty-six forms at first, ! and ? in 2004; the 28 below are drawn from scratch as inline SVG — no font, no sprite — each decoding twice: borrowed lore, the mechanism it stands for.

one of twenty-eight ·
the rest are in the wall
As of Legends: Z-A there is no Pokédex entry for it at all.

Availability

hover or focus to decode · click to pin and rain the letter · psst, try ↑↑↓↓←→←→ba

form 21 / 28 · U

U

form 21 / 28

Its name is “unknown” with the spelling knocked about; in Japanese it is simply アンノーン.
PokémonDB · Bulbapedia

in unown

Unknown. Point Unown at any endpoint you are allowed to use.

10 provider tiles on the model band

Every line under in unown describes something that runs here. Game-text quotations appear for commentary, sources named; no Pokémon sprite, card, logo or audio is bundled or reproduced. Open-source project — not affiliated with, endorsed by or sponsored by Nintendo, Game Freak, Creatures Inc. or The Pokémon Company. Pokémon and Unown remain their owners' trademarks.

FAQ

The skeptic's questions.

Including the one that decides installs.

Changelog

What has been added, and when.

599 entries, fromCHANGELOG.md. Dates from its headings, titles from its bullets; nothing written here.
  1. v0.0.68

    latest

    6 additions · 8 fixes · 29 alter agent behavior

    • A2H-9 — the encore Finale test-isolation fix (2026-11-06)

    v0.0.68 release+34 more

  2. v0.0.67

    1 addition · 1 fix

    • The evidence lane: every learned rule links back to its source note (the Memory Nocturne round)

    v0.0.67 release

  3. v0.0.66

    1 addition · 2 fixes

    • unown memory export / import — the memory interchange, behind the human gate (Divertimento CP6)

    v0.0.66 release

  4. v0.0.65

    2 additions · 8 fixes

    • The memory review queue — the human gate for inferred user-tier rules (Divertimento CP1)

    v0.0.65 release+1 more

  5. v0.0.64

    5 additions · 2 alter agent behavior

    • Memory v2 — bi-temporal supersede

    v0.0.64 release+6 more

  6. v0.0.63

    4 additions · 2 fixes · 1 alter agent behavior

    • Freshness lane — stale past 28 days

    v0.0.63 release+4 more

  7. v0.0.62

    6 additions · 8 fixes · 4 alter agent behavior

    • Memory Recital — the real-user benchtest

    v0.0.62 release+9 more

  8. v0.0.57

    2 fixes

      v0.0.57 release

    • v0.0.56

      1 fix

        v0.0.56 release

      • v0.0.55

        1 change · 2 fixes

          v0.0.55 release

        • v0.0.54

          2 changes · 1 fix

            v0.0.54 release

          • v0.0.53

            1 change · 3 fixes · 1 alter agent behavior

            • The todo tool is excluded while planning

            v0.0.53 release

          • v0.0.52

            6 additions · 4 fixes

            • The Interface section

            v0.0.52 release+5 more

          • v0.0.51

            6 fixes · 1 alter agent behavior

            • Plan-mode curl is read-only

            v0.0.51 release

          • v0.0.50

            10 additions · 4 fixes · 2 alter agent behavior

            • Plan file

            v0.0.50 release+11 more

          • v0.0.49

            7 additions · 3 fixes · 2 alter agent behavior

            • /abort

            v0.0.49 release+8 more

          • v0.0.48

            9 additions · 4 fixes · 1 alter agent behavior

            • The process registry

            v0.0.48 release+9 more

          • v0.0.47

            9 additions · 2 fixes · 1 alter agent behavior

            • The detection cascade

            v0.0.47 release+9 more

          • v0.0.46

            12 additions · 5 fixes · 2 alter agent behavior

            • The why field on every delegation

            v0.0.46 release+13 more

          • v0.0.45

            7 additions · 2 fixes

            • The mission panel

            v0.0.45 release+6 more

          • v0.0.44

            5 additions · 2 fixes

            • The Website Excellence Round 2 opens

            v0.0.44 release+4 more

          • v0.0.43

            8 fixes

              v0.0.43 release

            • v0.0.42

              3 additions · 5 fixes · 1 alter agent behavior

              • Encore — the gallery's eighth app, the Website Excellence showcase

              v0.0.42 release+3 more

            • v0.0.41

              2 additions · 5 fixes

              • Nocturne — the gallery's seventh app, an AI-native incident operations platform

              v0.0.41 release+1 more

            • v0.0.40

              4 additions · 5 fixes · 3 alter agent behavior

              • The validation round — the cold-start validation programme

              v0.0.40 release+6 more

            • v0.0.39

              5 additions · 4 fixes

              • The live-demo gallery's fifth app, Fugue

              v0.0.39 release+4 more

            • v0.0.38

              2 additions · 1 alter agent behavior

              • landing: the "Built & Improved With Unown" band

              v0.0.38 release+2 more

            • v0.0.37

              1 addition

              • landing: the carving round — the letters draw themselves

              v0.0.37 release

            • v0.0.36

              1 addition

              • landing: the presence round — the page answers the visitor

              v0.0.36 release

            • v0.0.35

              1 addition · 1 fix

              • landing + demo: the cadence round — a third app

              v0.0.35 release

            • v0.0.34

              3 additions · 2 fixes

              • landing + demo: the commerce round — the band became a gallery

              v0.0.34 release+2 more

            • v0.0.33

              3 additions · 2 fixes

              • landing + demo: the live preview round — the agent-built app, live

              v0.0.33 release+2 more

            • v0.0.31

              2 additions · 3 fixes · 4 security fixes

              • benchmarks: the long-run round — eleven duration scenarios, bench-owned anti-tamper scoring

              v0.0.31 release+1 more

            • v0.0.29

              1 addition · 3 changes

              • engine: browser dialog — native dialogs become answerable

              v0.0.29 release

            • v0.0.28

              1 addition · 1 change · 2 fixes

              • engine: the hardening round — the detached engine's verdict

              v0.0.28 release

            • v0.0.27

              2 additions · 1 security fix

              • subagents: stress round four — sync-lane pid-kill orphans

              v0.0.27 release+1 more

            • v0.0.26

              1 addition · 1 change · 1 fix

              • subagents: stress round three — the ledger's unpaid edges

              v0.0.26 release

            • v0.0.25

              1 addition

              • subagents: stress round two — chaos scenarios, seven live findings

              v0.0.25 release

            • v0.0.24

              2 additions

              • subagents: the stress round — ten scenarios, six findings, six fixes

              v0.0.24 release+1 more

            • v0.0.23

              2 changes · 1 fix

                v0.0.23 release

              • v0.0.22

                1 addition · 2 fixes

                • benchmarks: the memory-eval SOTA round

                v0.0.22 release

              • v0.0.21

                1 addition · 1 change · 1 fix

                • release: the second re-cut — the true macOS root cause is found

                v0.0.21 release

              • v0.0.20

                2 additions

                • release: the learning-integrity round re-cuts

                v0.0.20 release+1 more

              • v0.0.19

                1 addition · 1 change · 1 fix

                • cli: the install receipt reaches the TUI

                v0.0.19 release

              • v0.0.18

                1 addition · 1 change · 4 fixes

                • ci: the xplat lane — cross-platform testing an agent can drive

                v0.0.18 release

              • v0.0.17

                1 fix

                  v0.0.17 release

                • v0.0.16

                  13 additions

                  • landing: the blog — the longhand record

                  v0.0.16 release+12 more

                • v0.0.15

                  3 additions

                  • release: v0.0.15 — the media-completion round ships

                  v0.0.15 release+2 more

                • v0.0.14

                  1 addition

                  • release: the parity round re-cuts — v0.0.14 supersedes the failed v0.0.13 tag

                  v0.0.14 release

                • v0.0.13

                  6 additions · 1 fix

                  • parity: session workflow — markdown export, both stores

                  v0.0.13 release+5 more

                • v0.0.12

                  1 addition

                  • release: the pending-plates round ships with the Windows release-gate fixes

                  v0.0.12 release

                • v0.0.11

                  1 addition

                  • landing: the pending-plates round — every capability filmed, no duplicate faces

                  v0.0.11 release

                • v0.0.10

                  4 additions · 1 fix

                  • parity: the trust round — in-session permission modes + additional working directories

                  v0.0.10 release+3 more

                • v0.0.9

                  1 addition

                  • browser-subagent: automation as a first-class subagent

                  v0.0.9 release

                • v0.0.8

                  1 addition

                  • parity: the 2026 consensus round — /btw, /output-style, /insights, session auto-titles…

                  v0.0.8 release

                • v0.0.7

                  6 additions · 2 fixes

                  • landing: three filmed gaps closed, the hard way

                  v0.0.7 release+5 more

                • v0.0.6

                  1 addition · 1 fix

                  • browser(v2): the stealth + CAPTCHA tiers

                  v0.0.6 release

                • v0.0.5

                  1 addition · 3 changes · 5 fixes · 2 alter agent behavior

                  • browser automation: the browser session tool — real Chromium over raw CDP

                  v0.0.5 release+2 more

                • v0.0.4

                  19 additions · 5 changes · 1 removal · 24 fixes · 8 alter agent behavior

                  • landing: a section menu below lg — the anchors back on phones

                  v0.0.4 release+26 more

                • v0.0.3

                  8 additions · 7 fixes · 13 alter agent behavior

                  • onboarding 2.0 — the Hermes-patterned first run and setup wizard

                  v0.0.3 release+20 more

                • v0.0.2

                  5 additions · 3 changes · 10 fixes

                  • a verified standalone binary install lane (--binary / -Binary)

                  v0.0.2 release+4 more

                • v0.0.1

                  54 additions · 7 changes · 2 removals · 53 fixes · 8 alter agent behavior

                  • a cloned repo can no longer masquerade as AutoDream: provenance + the injection scan

                  v0.0.1 release+60 more

                Newest left; cut releases recede right. Scroll or ◀ ▶.

                Where to start

                One afternoon, and then it starts remembering.

                Clone it, run one session, come back tomorrow to memory that knows what you told it. Nothing to sign up for; if it is not useful, you have lost an afternoon.
                7/9

                UNKNOWN

                If a letter is missing from your keyboard, ! and ? always work.